Big Idea 3: Programming and Algorithms
The Concept of Abstraction in Computer Science
Abstraction is a fundamental concept in computer science that involves representing essential features without including unnecessary details. It simplifies the complexity of systems, making it easier to design and implement software. Abstractions are crucial as systems grow more intricate.
Example of Abstraction in Daily Use: When you check stories on Instagram, numerous processes occur in the background. Abstractions allow you to interact with the app seamlessly, focusing on the content rather than the underlying technical operations. This means you can send a message or post a photo without needing to understand the network protocols, data encryption, or server interactions that make it all possible.
Programming and Abstractions
Purpose of Abstraction: In programming, abstraction serves to hide the coding details, allowing programmers to concentrate on solving the current problem without getting bogged down by the underlying complexities.
Machine Code vs. High-Level Programming Languages:
- Machine Code: The fundamental language understood by computers, consisting strictly of binary numbers. It is fast but extremely difficult for humans to write and understand directly.
- High-Level Languages: Languages like Python and Java offer higher levels of abstraction, making programming more accessible and understandable. These languages are closer to human language, which simplifies the coding process.
Common Abstractions on the AP Exam
Procedural Abstraction: Procedural abstraction involves grouping code into procedures or functions, which enhances readability and reusability. It allows programmers to use these procedures without knowing the details of how they operate.
Procedural Abstraction Examples on the AP Exam
1. DISPLAY(expression)
- Explanation: This abstraction is used to display the value of an expression. It abstracts away the details of output mechanisms, enabling students to focus on what is being output rather than how it's being displayed.
2. RANDOM(a, b)
- Explanation: This function generates a random number between the integers a and b (inclusive). It abstracts the complexity of random number generation, providing a simple interface for getting random values.
Variables
Big Idea 2 (Understanding Variables and Data Types) covers what a variable is and the number, Boolean, and list types. Remember that a variable holds only one value at a time, though that one value can be a whole list. The AP exam also uses strings: text in quotes, like "Hello" (see Strings below).
- Choosing the Right Type: Some values fit one type better than another. A phone number or ZIP code should be a string, not a number, because you never do math with it, and a ZIP code like 02134 would lose its leading zero if stored as a number. Whether a light is on fits a Boolean (true or false) better than the strings "yes" and "no".
- Meaningful Names: Name variables after what they hold. highScore and numStudents tell the reader what the values mean, while x and temp2 make the code harder to read and understand.
Assignment Using Arrows
In some programming languages and pseudocode, the arrow ( ← ) is used to denote assignment, which assigns the value of an expression to a variable. This is what the AP exam uses. Be careful: languages like Python and Java use = for assignment, but on the AP exam = never assigns anything. It only checks whether two values are equal.
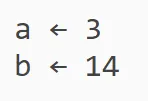
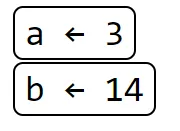
How Assignment Works: a ← expression first evaluates the expression, then stores a copy of the result in a. That's why count ← count + 1 works: the computer figures out count + 1 using the old value, then saves the answer back into count. Assigning a new value replaces the old one, so a variable always holds the most recent value assigned to it.
a ← 1
b ← a
a ← 2
DISPLAY(b)
This displays 1, not 2. When b ← a runs, b gets a copy of the value in a (which is 1 at that moment). Changing a afterward doesn't change b.
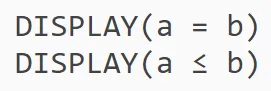
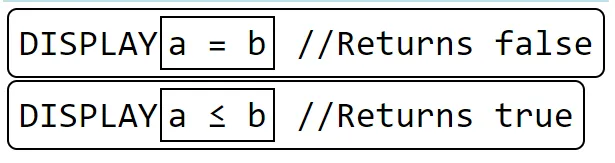
Displaying Boolean Evaluations
Relational Operators
Relational operators (also called comparison operators) are used to compare two values or expressions. The result of such a comparison is a Boolean value, true or false.
Explanation: Each operator allows for different types of calculations or comparisons:
- Arithmetic operators (+, -, *, /, MOD) perform mathematical operations.
- Relational operators (=, ≠, <, >, ≤, ≥) compare values, useful in control flow and decision-making processes.
Chart of Common Operators and Their Uses:
Operator | Meaning | Example |
+ | Addition | 3 + 2 // 5 |
- | Subtraction | 3 - 2 // 1 |
* | Multiplication | 3 * 2 // 6 |
/ | Division | 3 / 2 // 1.5 |
MOD | Modulus (remainder) | 3 MOD 2 // 1 |
= | Equal to | 4 = 5 // false |
≠ | Not equal to | 4 ≠ 5 // true |
< | Less than | 4 < 5 // true |
> | Greater than | 5 > 4 // true |
≤ | Less than or equal to | 4 ≤ 6 // true |
≥ | Greater than or equal to | 8 ≥ 9 // false |
Note: On the AP exam, / is regular division, so the answer can be a decimal: 17 / 5 evaluates to 3.4. It doesn't drop the decimal part the way integer division does in some languages.
Modulus Operator Example
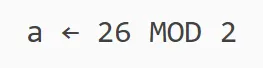
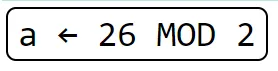
Explanation of the Value of a: The modulus operator finds the remainder of the division of one number by another. In this case, 26 MOD 2 calculates the remainder when 26 is divided by 2, which is 0, since 26 is evenly divisible by 2.
Tutorial to Calculate Modulus Value
How to Calculate the Modulus:
- Divide the left number by the right number.
- The modulus value is the remainder of this division.
Special Cases:
- Example: a ← 3 MOD 4
- Explanation: If the divisor is larger than the dividend (3 divided by 4), the remainder is the dividend itself, so a would be 3.
- Dividing by Zero: a ← 6 MOD 0
- Result: This operation will result in an error as division by zero is undefined in mathematics and programming. If this was the other way around, it would be 0.
- Another Example: 17 MOD 5
- Explanation: 5 goes into 17 three times (15), with 2 left over, so 17 MOD 5 evaluates to 2.
- Checking Divisibility: If a MOD b is 0, there's no remainder, so a is evenly divisible by b. A number is even when num MOD 2 is 0 and odd when num MOD 2 is 1.
Order of Operations: PEMDAS
In programming, the order of operations follows the well-known PEMDAS rule:
- Parentheses
- Exponents
- Multiplication and Division (from left to right)
- Addition and Subtraction (from left to right)
- Modulus is treated like division and multiplication in terms of precedence.
Expressions
An expression is anything that evaluates to a single value. It can be a value (like 7), a variable (like score), values and variables joined by operators (like score + 7), or a procedure call that returns a value (like RANDOM(1, 6)). The computer always boils an expression down to one value, following the order of operations above.
- Example: 2 + 3 * 4 MOD 5 evaluates to 4. Multiplication and MOD go first, left to right: 3 * 4 is 12, then 12 MOD 5 is 2. Then 2 + 2 is 4.
Variable Assignment and Reassignment Example
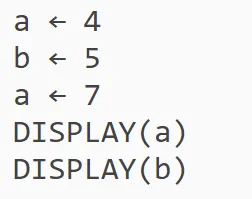
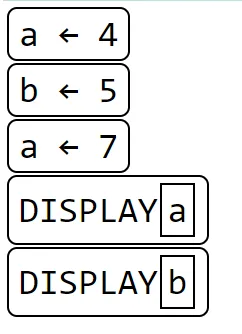
Explanation: This example shows how variables can be set and then changed within a program. Understanding that the latest assignment is what defines the variable’s value is crucial.
Output: 7 5. The variable a is set to 4, then reassigned to 7, so DISPLAY(a) shows 7. The variable b was set to 5 and never changed. (DISPLAY shows a value followed by a space, so both values show up on the same line.)
Practice Questions: Basic Arithmetic in Programming
Question 1: Calculate a if a ← (5 + 3) * 2 MOD 3
- Calculation: First, add 5 and 3 to get 8, multiply by 2 to get 16, and then take 16 MOD 3 which gives a remainder of 1.
- Answer: a is 1.
Question 2: What is the value of b if b ← 10 - 6 / 3
- Calculation: Division first, 6 / 3 equals 2, then subtraction, 10 - 2 equals 8.
- Answer: b is 8.
Strings
A string is an ordered sequence of characters, like "Hello" or "AP CSP". Letters, spaces, digits, and punctuation all count as characters. Just like a list, each character has an index, and on the AP exam the first character is at index 1.
String Concatenation
Concatenation joins two or more strings end to end to make a new string. It doesn't add a space for you. The AP reference sheet doesn't list any string procedures, so an exam question will describe the one it uses, for example concat(str1, str2), which returns str1 followed by str2. (In many languages, like Python and JavaScript, + joins strings.)
greeting ← concat("Hello", "World")
DISPLAY(greeting)
greeting ← concat(concat("Hello", " "), "World")
DISPLAY(greeting)
The first DISPLAY shows HelloWorld. The second shows Hello World, because the space was joined in as its own string.
Substrings
A substring is part of an existing string. For example, "put" is a substring of "computer". A question might define substring(str, start, length), which returns length characters of str, starting at index start.
word ← "APCSP"
DISPLAY(substring(word, 3, 3))
This displays CSP: the characters at indexes 3, 4, and 5. Always read how the question defines its string procedures, since some versions use an ending index instead of a length.
Understanding Percentage Chance in Programming with Examples
Example 1: Calculating Percentage Chance for a Single Event
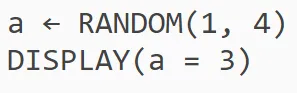
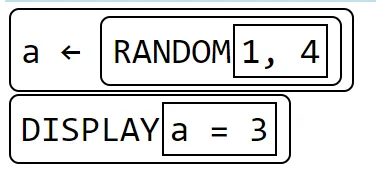
Question: What is the percentage chance that a equals 3?
Explanation:
- Total Possible Selections: 1, 2, 3, 4
- Favorable Outcome: The number 3
- Calculation: There is one favorable outcome (3) out of four possible outcomes, so the chance is 1/4 which converts to 25%.
- Percentage Chance: 25%
This calculation reflects basic probability principles where the likelihood of an event occurring is the ratio of favorable outcomes to the total number of possible outcomes.
Example 2: Calculating Percentage Chance for Multiple Favorable Outcomes
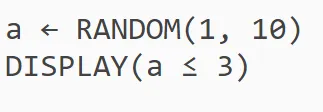
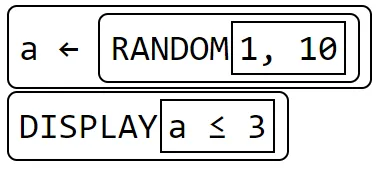
Question: What is the percentage chance that a is less than or equal to 3?
Explanation:
- Total Possible Selections: 1 through 10
- Favorable Outcomes: 1, 2, 3
- Calculation: There are three favorable outcomes (1, 2, 3) out of ten possible outcomes, so the chance is 3/10.
- Percentage Chance: 30%
In this case, because there are three numbers (1, 2, and 3) that satisfy the condition a <= 3 out of ten possible numbers, the probability is 30%. This example teaches how to account for multiple favorable outcomes when calculating the likelihood of an event.
Key Points About RANDOM
- Whole Numbers, Equally Likely: RANDOM(a, b) returns a random integer from a to b, inclusive, and every value in that range is equally likely. RANDOM(1, 3) could return 1, 2, or 3, each with a 1 in 3 chance.
- Different Every Run: Because of RANDOM, the same program can give a different result each time it runs. That's why exam questions ask for the possible outputs of a program.
- Finding Possible Values: Work out the range of RANDOM first, then apply the rest of the expression. RANDOM(1, 3) * 2 can only be 2, 4, or 6. RANDOM(0, 4) + 10 can be any whole number from 10 to 14.
Simulations
A simulation is an abstraction of a more complex object or event, built for a specific purpose. It uses changing sets of values to show the changing state of whatever it models. A traffic simulation, for example, keeps track of where every car is and updates those positions over and over to show how traffic flows.
- Why Use Simulations: They let you study something without the limits of the real world and draw conclusions (inferences) from the results. They're most useful when a real experiment is impractical because it's too big, too small, too fast, too slow, too expensive, or too dangerous, like the spread of a disease through a whole country, climate change over 100 years, or crash testing hundreds of car designs.
- Simplifying: Building a simulation means removing specific details or simplifying how things work. A traffic simulation might treat every car as the same size and ignore the weather.
- Bias: A simulation can be biased by which real-world elements were included or left out. If that traffic simulation ignores accidents and road construction, it will predict smoother traffic than drivers actually see.
- Testing Hypotheses: Simulations help people form and refine hypotheses. A scientist can change one value (like a disease's infection rate), run the simulation again, and see how the outcome changes.
- Randomness: Random number generators are used to simulate the variability of the real world, like whether a coin lands heads, whether a customer shows up in the next minute, or whether a person catches a disease.
Example: Simulating Coin Flips
heads ← 0
REPEAT 100 TIMES
{
   IF(RANDOM(1, 2) = 1)
   {
      heads ← heads + 1
   }
}
DISPLAY(heads)
Explanation: Each pass through the loop is one flip, and RANDOM(1, 2) = 1 counts as heads. The program displays how many of the 100 flips were heads. The answer is usually close to 50, but it changes every time the program runs, just like flipping a real coin 100 times. The computer can run this thousands of times in the time it takes you to flip a real coin once.
Concept of Data Abstraction
Data abstraction is a fundamental concept in computer science that involves separating the abstract properties of a data type from the concrete details of its implementation. This separation simplifies complex systems by enabling programmers to work with data collections under a unified interface without needing to know the specifics of their storage or representation.
Lists as Data Abstractions
Definition and Usage: Lists (also known as arrays in some programming languages) allow multiple related items to be grouped together and treated as a single entity. This grouping simplifies operations that involve multiple data points, such as calculations, sorting, and searching.

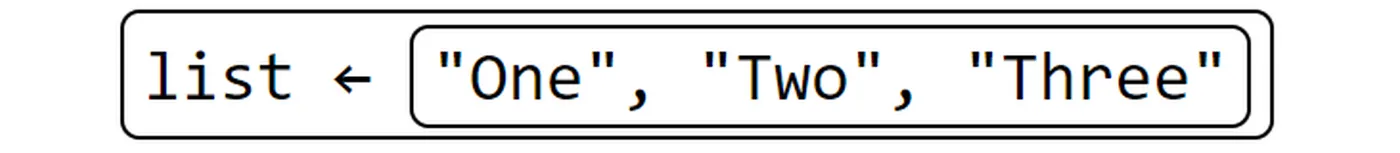
Lists enhance readability and manageability of code by reducing the need for multiple individual variables and allowing complex data manipulations through built-in methods and functions.
Why are Lists important?
Say a program needs the test scores of 30 students. Without a list, you'd need 30 separate variables (score1, score2, and so on up to score30), and finding the average would mean typing out all 30 names. If a 31st student joins, you'd have to add a new variable and change every line that uses them. With a list, one name, scores, holds every score. A loop can go through it no matter how long it is, and adding a student is just APPEND(scores, 88).
Using a list simplifies these operations by providing a flexible and efficient way to store, access, and manipulate data. Lists enable easier implementation of functions and operations over the data set, significantly reducing the complexity and enhancing the maintainability of the program.
- Naming a Collection: A data abstraction manages complexity by giving a whole collection of data one name, without referring to the details of how it's stored. You work with scores, not with 30 separate values.
- Mixed Types: Data abstractions often contain different types of elements. A list describing a book could be ["Beloved", "Toni Morrison", 1987, true], which mixes strings, a number, and a Boolean.
Basic Concepts of Lists
Lists are structured collections that store data in an organized manner, allowing for efficient data retrieval and manipulation. Each element in a list is assigned a unique index, which can be used to access the element directly.
Indexing in Lists
- In many programming languages like Python and JavaScript, indexing starts at 0. However, on the AP Computer Science Principles exam, lists are indexed starting at 1.
- Accessing an element by its index is straightforward: listName[index] retrieves the element at that specific position.
- Creating a List: aList ← [value1, value2, value3] creates a list with those values at indexes 1, 2, and 3 and assigns it to aList. aList ← [] creates an empty list.
- Copying a List: aList ← bList assigns a copy of bList to aList. If bList contains [20, 40, 60], then aList will also contain [20, 40, 60] after the assignment.
scores ← [11, 35, 6, 75, 37]
scores[1]   // 11
scores[2]   // 35
In this example, scores[1] accesses the first element of the list, which is 11, adhering to the AP exam's indexing rule.
Handling Index Out of Bounds Errors
When you try to access an index that is less than 1 or greater than the length of the list, it results in an "index out of bounds" error. On the AP exam, attempting to access a non-existent index will terminate the program, unlike some programming languages that might return undefined or throw an exception without terminating the program.
Inserting Elements into a List
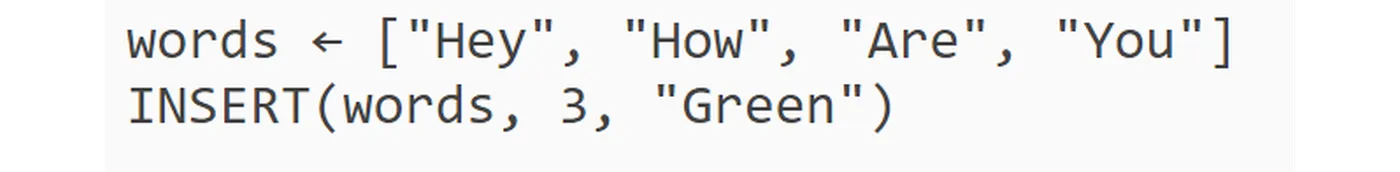
The INSERT(list, i, item) function is used to insert an item into the list at a specified index i. This function modifies the list by placing the new item at the index i and shifting elements at index i and higher to the right.
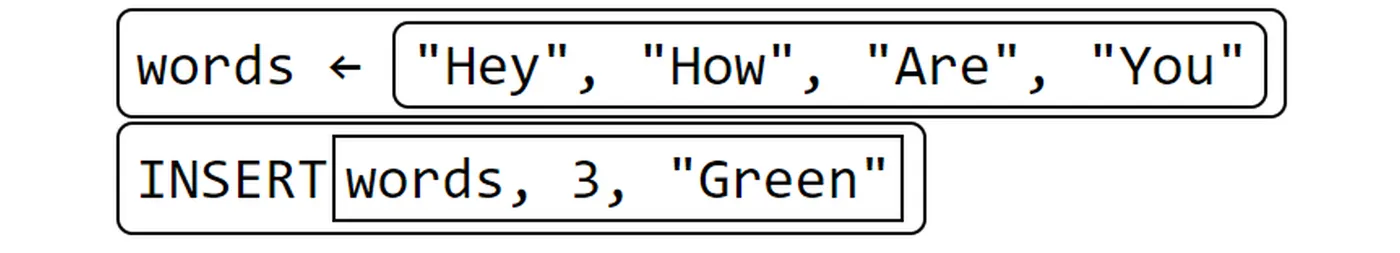
Explanation of What This Does:
- Before Insertion: The list words contains ["Hey", "How", "Are", "You"]
- After Insertion: The item "Green" is inserted at the third position:
- New list after insertion: ["Hey", "How", "Green", "Are", "You"]
The element "Green" is added to the list at index 3, while "Are" (previously at index 3) and "You" (previously at index 4) are shifted right to indices 4 and 5, respectively.
List Operations in Programming: Append, Insert, and Remove
Demonstrating List Operations with Examples
Given an initial setup and a series of operations, let's walk through how these modify a list. The operations we will explore are APPEND, INSERT, and REMOVE.
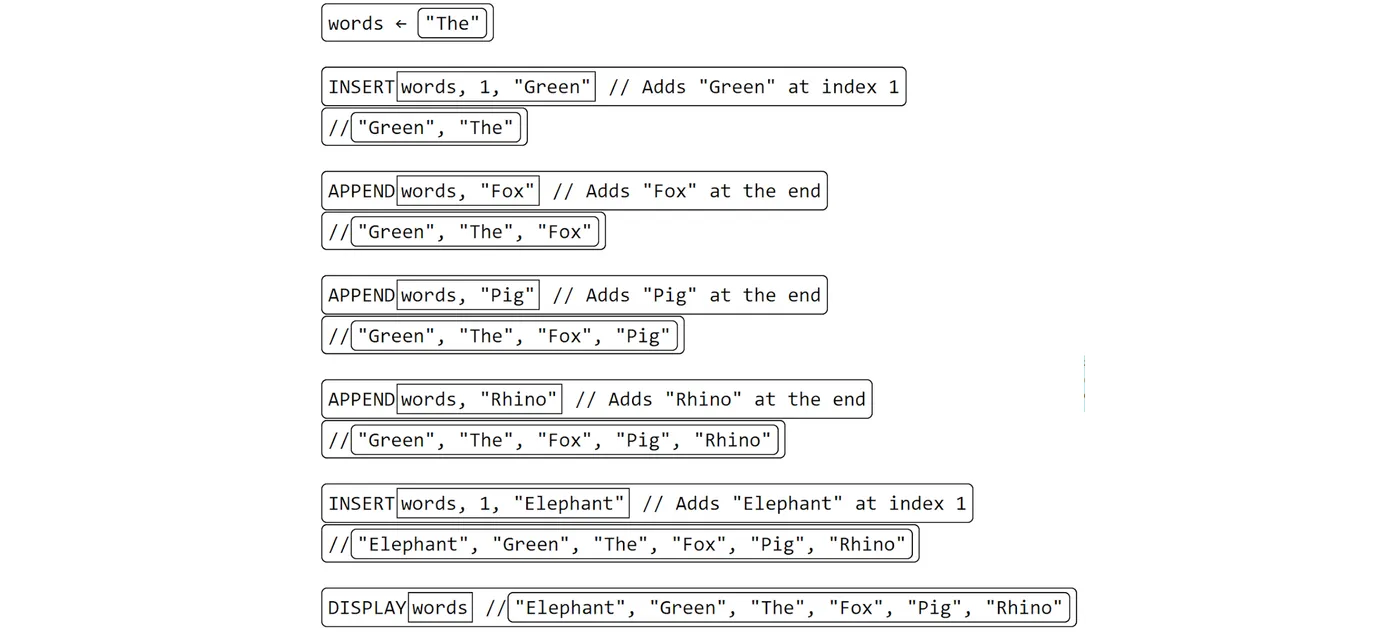
Using REMOVE
REMOVE(words, 1)   // Removes the item at index 1
// ["Green", "The", "Fox", "Pig", "Rhino"]
REMOVE(words, 3)   // Removes the item at index 3
// ["Green", "The", "Pig", "Rhino"]
Explanation of What Happened:
Initial List Operations:
- The INSERT operations place new elements at specified positions within the list, pushing existing elements to the right.
- The APPEND operations add new elements to the end of the list, extending the list's size.
Removal Operations:
- The REMOVE function deletes an element at a specified index. The first REMOVE operation deletes "Elephant" from the list, and subsequent elements shift left to fill the gap.
- The second REMOVE operation, adjusted after the list has been altered by the first removal, deletes "Fox." Again, the remaining elements shift left, compacting the list further.
All the List Operations on the AP Reference Sheet
Operation | What It Does |
aList[i] | Accesses the element at index i. The first element is aList[1]. |
x ← aList[i] | Assigns the value of aList[i] to the variable x. |
aList[i] ← x | Assigns the value of x to aList[i], replacing what was there. |
aList[i] ← aList[j] | Assigns the value of aList[j] to aList[i]. |
INSERT(aList, i, value) | Shifts the values at index i and higher one spot to the right, then puts value at index i. The length goes up by 1. |
APPEND(aList, value) | Puts value at the end of aList. The length goes up by 1. |
REMOVE(aList, i) | Removes the item at index i and shifts the values after it one spot to the left. The length goes down by 1. |
LENGTH(aList) | Evaluates to the number of elements currently in aList. |
Every language has these operations, but the names and syntax follow that language's rules. Adding to the end of a list is APPEND on the AP exam, append() in Python, and push() in JavaScript. And for any of them, using an index less than 1 or greater than LENGTH(aList) causes an error and ends the program.
Algorithms and Sequencing
An algorithm is a finite set of instructions that accomplishes a specific task. A recipe, directions to a friend's house, and the steps for finding the largest number in a list are all algorithms.
- Ways to Express an Algorithm: Algorithms can be written in natural language (plain English), as diagrams like flowcharts, in pseudocode like the AP exam's, or in a visual (block) or text-based programming language. To run on a computer, an algorithm has to be implemented in a programming language.
- The Three Building Blocks: Every algorithm can be built from some combination of sequencing, selection (conditionals), and iteration (loops). Selection and iteration are covered in the next sections.
- Sequencing: Carrying out each step of an algorithm in the order the code statements are given. A code statement is a part of program code that expresses an action to be carried out, like an assignment or a DISPLAY. Statements run one after another, top to bottom, unless a conditional, a loop, or a procedure call changes the flow.
- Clarity and Readability: The same algorithm can be written many ways, so write it in a way others can follow: meaningful names, consistent indenting, and steps in a logical order.
Example: Order Matters
x ← 5
y ← x + 2
x ← 10
DISPLAY(x)
DISPLAY(y)
Output: 10 7. y was calculated while x was still 5, so y is 7, and changing x later doesn't go back and change y. If you swapped the first and third lines, the output would be 5 12.
Understanding Conditionals in Programming
What are Conditionals?
Conditionals are fundamental constructs in programming that allow you to make decisions in your code based on whether certain conditions are true or false. They are used to execute different blocks of code based on different inputs or states of the program.
Using a condition to decide which parts of an algorithm run is called selection. Conditional statements ("if-statements") change the normal top-to-bottom flow of a program: depending on whether a Boolean expression is true or false, some statements run and others are skipped.
Structure of Conditionals
The basic structure of a conditional in most programming languages, including JavaScript, involves an if statement possibly followed by an else statement:
IF(condition)
{
   DISPLAY("Condition met")
}
ELSE
{
   DISPLAY("Condition not met")
}
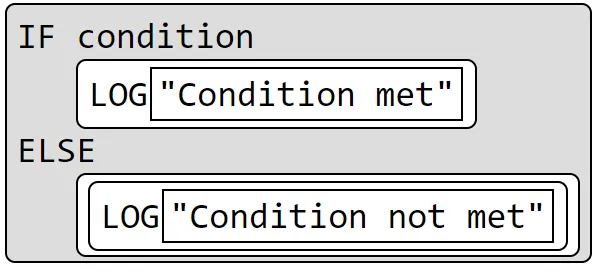
On the AP exam, conditionals use the reference sheet's notation (and DISPLAY instead of LOG). There are two forms:
IF(condition)
{
   <block of statements>
}
- IF: The block of statements runs only if condition evaluates to true. If it's false, nothing happens and the program moves on to the next statement.
IF(condition)
{
   <first block of statements>
}
ELSE
{
   <second block of statements>
}
- IF / ELSE: If condition is true, the first block runs. Otherwise, the second block runs. Exactly one of the two blocks always runs.
Relational Operators Used in Conditions
Relational operators (also called comparison operators) are used within conditions to compare expressions. In JavaScript, these include:
- == or ===: Equality and strict equality
- != or !==: Inequality and strict inequality
- <: Less than
- >: Greater than
- <=: Less than or equal to
- >=: Greater than or equal to
These operators evaluate the relationship between two values or expressions and return a Boolean value (true or false), which determines which block of code the conditional executes.
On the AP exam, these operators are written as = (equal to), ≠ (not equal to), <, >, ≤, and ≥. There's no ==, ===, or !=, and a single = always means "is equal to," never assignment.
Examples of Conditional Statements
Example 1: Simple If-Else Statement
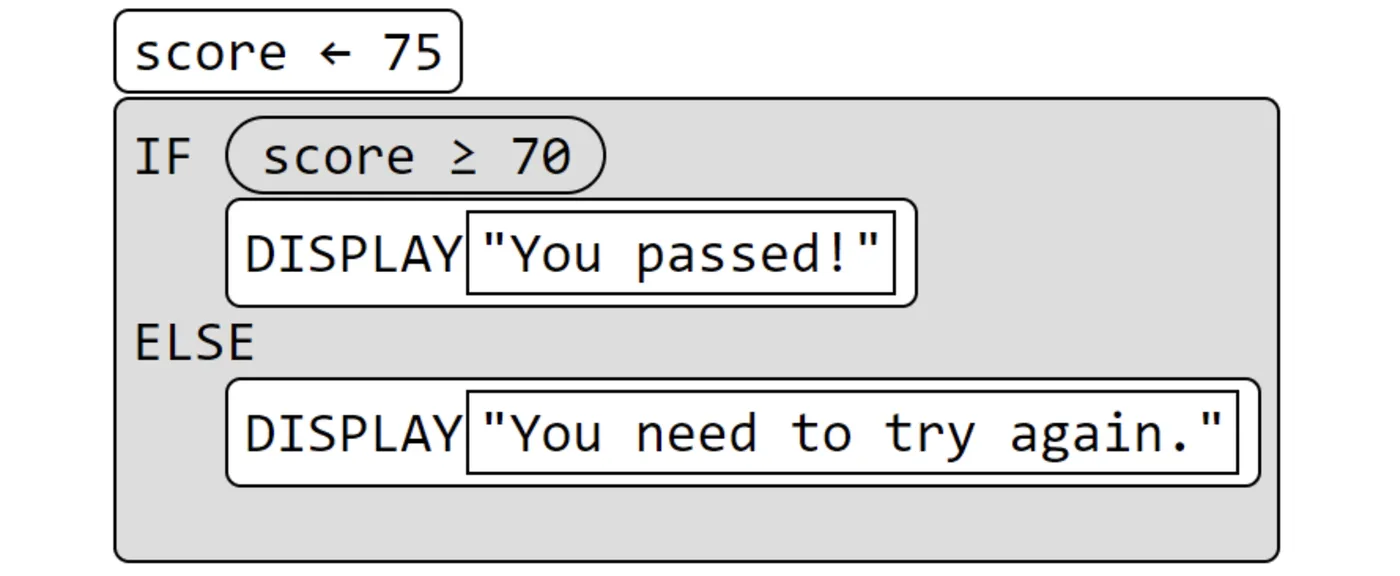
Explanation: The condition checks if the score is 70 or higher. If true, it prints "You passed!" If false, it prints "You need to try again."
Example 2: Using the Logical OR Operator
The logical OR operator is used in conditions to check if at least one of multiple conditions is true. It returns true if either condition (or both) evaluates to true, and false only when both are false.
Note: On the AP exam, OR is written in capital letters, like condition1 OR condition2. Languages like JavaScript and Java write it as ||.
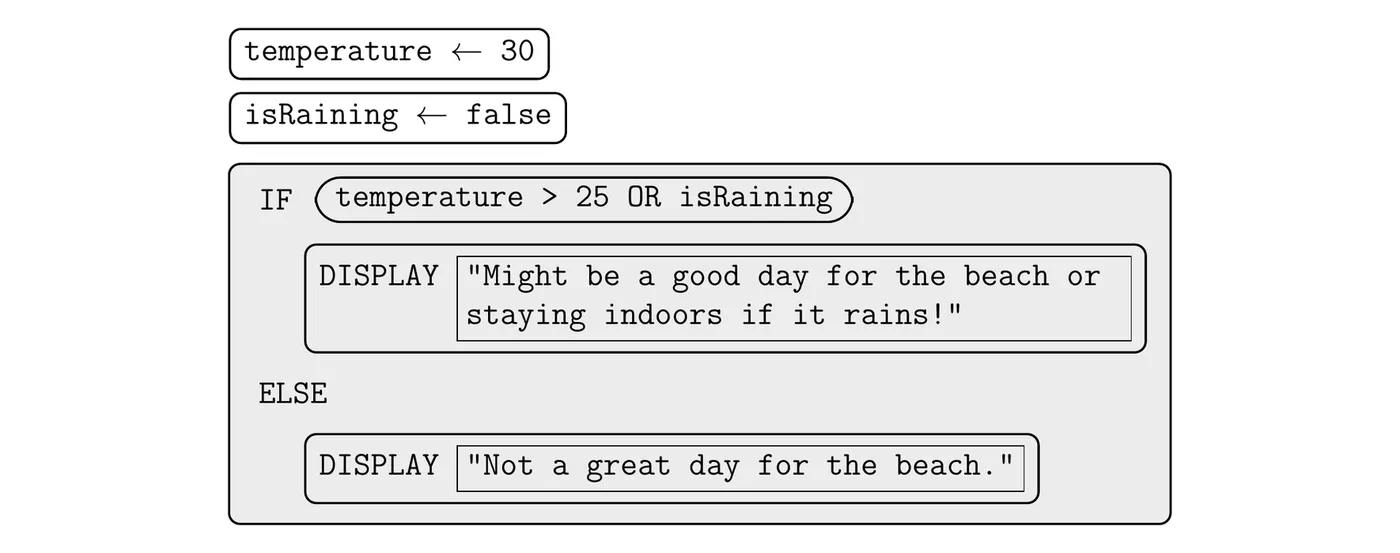
Explanation: temperature is 30, so temperature > 25 is true. isRaining is false. Since true OR false is true, the program displays "Might be a good day for the beach or staying indoors if it rains!"
Example 3: Using the Logical AND Operator
The logical AND operator is used in conditions to check if all of the given conditions are true. It returns true only if all conditions evaluate to true.
Note: On the AP exam, AND is written in capital letters, like condition1 AND condition2. Languages like JavaScript and Java write it as &&.
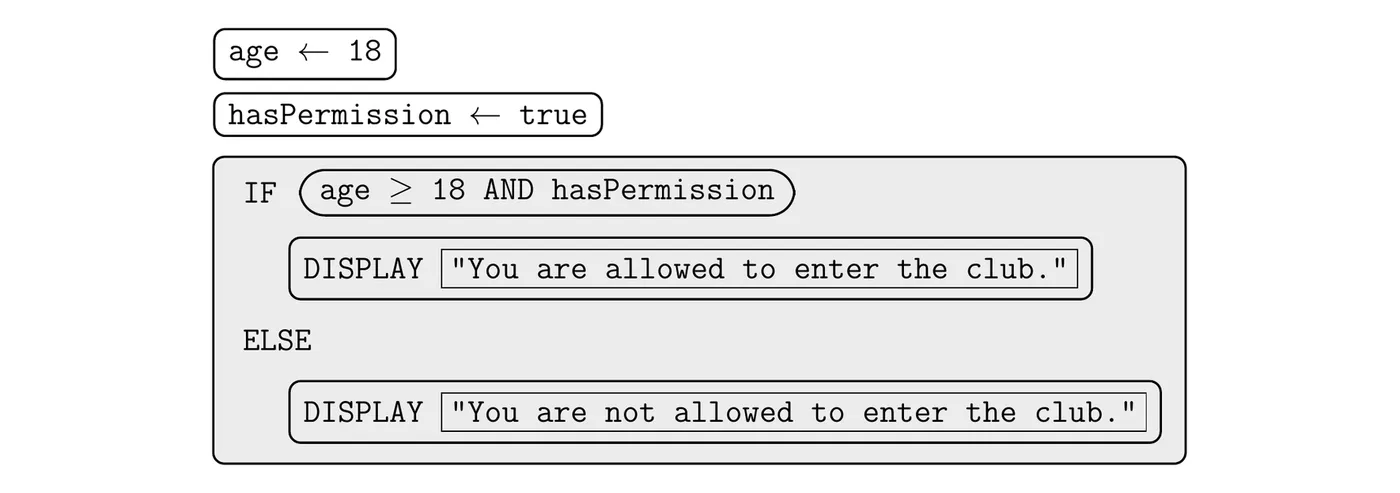
Explanation: This example checks if the individual is 18 years or older and if they have permission (perhaps from a parent or guardian). Both conditions must be true for the individual to be allowed to enter the club. If either condition is false, the individual will not be allowed entry.
Here age is 18, so age ≥ 18 is true, and hasPermission is true. Both conditions are true, so the program displays "You are allowed to enter the club."
Example 4: Using the Logical NOT Operator
The logical NOT operator flips a Boolean value. NOT condition evaluates to true if condition is false, and to false if condition is true.
isRaining ← false
IF(NOT isRaining)
{
   DISPLAY("No umbrella needed.")
}
Explanation: isRaining is false, so NOT isRaining is true, and the program displays "No umbrella needed."
Summary of the Logical Operators
A | B | A AND B | A OR B | NOT A |
true | true | true | true | false |
true | false | false | true | false |
false | true | false | true | true |
false | false | false | false | true |
- Operands: Each side of AND or OR, and whatever comes after NOT, must be a Boolean value or a Boolean expression, like isRaining or score ≥ 70. You can combine them: (age ≥ 13) AND (NOT isBanned) is true only for someone who is 13 or older and isn't banned.
Nested Conditionals
Nested conditional statements are conditional statements inside other conditional statements. The inner IF is only checked if the program reaches it, so nesting lets you make a decision that depends on an earlier decision.
temp ← 75
IF(temp > 90)
{
   DISPLAY("Hot")
}
ELSE
{
   IF(temp > 60)
   {
      DISPLAY("Warm")
   }
   ELSE
   {
      DISPLAY("Cold")
   }
}
Step-by-Step Trace:
- temp is 75. Is 75 > 90? No, so the program skips "Hot" and goes to the outer ELSE.
- Inside the ELSE, it checks the inner condition. Is 75 > 60? Yes.
- It displays Warm and skips the inner ELSE. Only one of the three DISPLAY statements can ever run.
Tip: Trace nested conditionals one level at a time, and cross out each block that gets skipped. With temp ← 40 instead, 40 > 90 is false and 40 > 60 is false, so the program displays Cold.
Understanding Loops in Programming
Iteration is a repeating portion of an algorithm. It repeats a set number of times or until a condition is met. Iteration statements change the normal top-to-bottom flow by running a set of statements zero or more times, until a stopping condition is met.
Loops are fundamental constructs in programming that allow repetitive tasks to be executed efficiently. Let's explore two common types of loops: the "Repeat n Times" loop and the "Repeat Until Condition" loop.
Loop 1: REPEAT n TIMES
This loop type executes a block of statements a specified number of times. This is a straightforward way to perform a task multiple times without manually writing the code repeatedly.
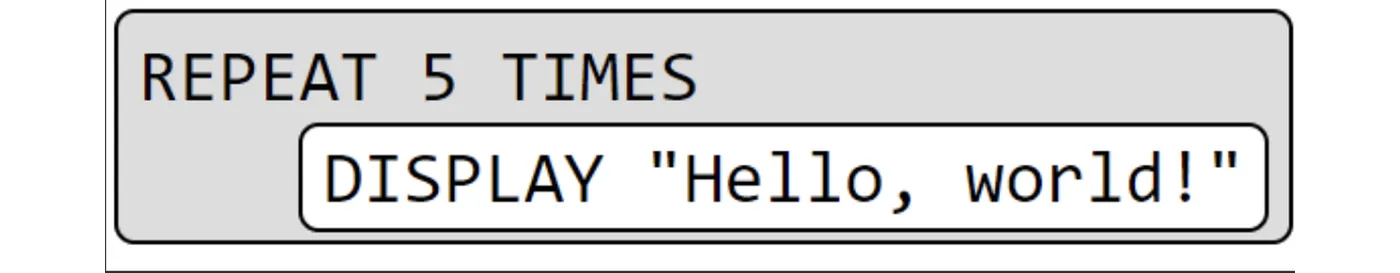
Explanation:
- Operation: The loop will execute the block of statements DISPLAY("Hello, world!") five times.
- Behavior: Each iteration prints "Hello, world!" to the screen, resulting in the message being displayed five times.
Loop 2: REPEAT UNTIL(Condition)
This loop continues to execute as long as a condition is false and stops once the condition becomes true. This is somewhat opposite to a typical while loop seen in languages like Python, which continues as long as the condition is true.
counter ← 1
REPEAT UNTIL(counter > 5)
{
   DISPLAY("Counter:")
   DISPLAY(counter)
   counter ← counter + 1
}
Explanation:
- Operation: The loop starts with counter set to 1 and repeats the block of statements until counter exceeds 5.
- Behavior: Inside the loop, it displays the current value of counter and then increments counter by 1. The loop stops when counter becomes 6, having printed values from 1 to 5.
Key Points to Remember:
- Relational Operators: These are used in the condition to compare expressions (e.g., counter > 5). These operators help determine whether the loop should continue or terminate.
- Loop Purpose: This type of loop is particularly useful when you need to perform actions until a certain condition is met, such as waiting for user input to reach a particular state or processing items until a condition changes.
- Infinite Loops: If a REPEAT UNTIL loop's ending condition never becomes true, the loop runs forever. This is called an infinite loop. In the code below, count goes 1, 3, 5, 7, 9, 11, and so on. It's never exactly 10, so the loop never ends.
count ← 1
REPEAT UNTIL(count = 10)
{
   count ← count + 2
}
- The Condition Is Checked First: REPEAT UNTIL checks its condition before each pass, including the very first one. If the condition is already true at the start, the loop body doesn't run at all. Below, x > 5 is true right away, so the loop is skipped and the program displays 10.
x ← 10
REPEAT UNTIL(x > 5)
{
   x ← x + 1
}
DISPLAY(x)
Practical Application of Loops
Loops are essential for managing repetitive tasks without unnecessary code duplication, enhancing the readability and maintainability of programs. Understanding how to effectively use different types of loops based on the scenario (e.g., knowing when to use a fixed number of iterations vs. waiting for a condition to change) is crucial for efficient programming.
Loop 3: Looping Through a List
Looping through a list or an array allows you to perform operations on each element in the collection sequentially. This type of loop, often referred to as a "FOR EACH" loop, is incredibly useful for handling collections of items without manually indexing each element.
Explanation of FOR EACH Loop
In a FOR EACH loop, a temporary variable is assigned to each element in the list, one at a time, from the first to the last. The block of statements within the loop then operates on each of these elements.
This structure simplifies operations on arrays or lists by abstracting the process of iterating over each element, thereby avoiding manual loop controls and index management.
Example: Logging Each Item in an Array
Let's take a practical look at how this works with an example.
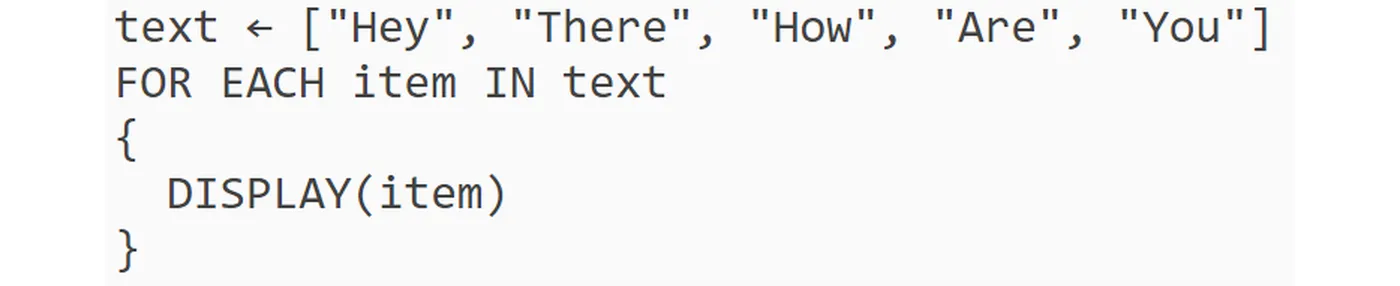
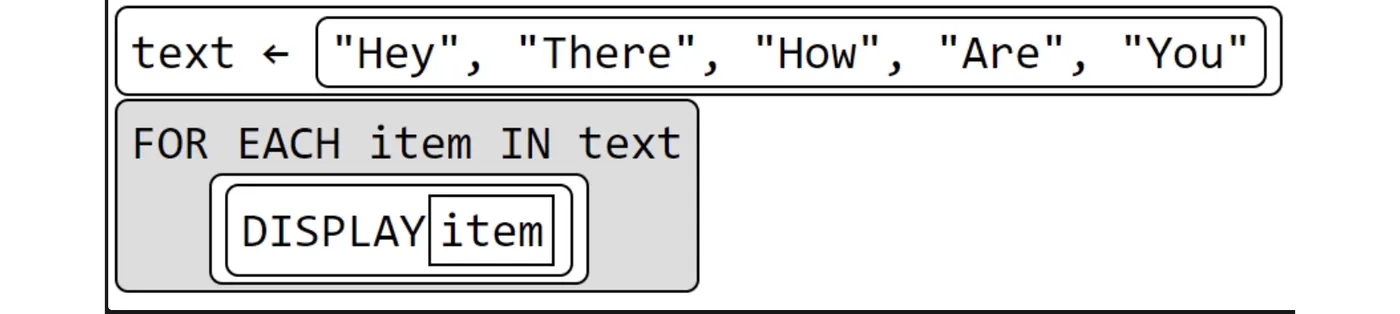
- Setup: The text array contains several words.
- Loop Operation: FOR EACH method is used here to iterate over each element in the text array.
- Function Execution: For each element, the DISPLAY function is called with item as the argument, which prints each word to the console.
- Output: Hey There How Are You (each DISPLAY adds a space after the word).
How It Works:
- Iteration: Each element in the array text is passed in turn to the function defined inside the forEach. The function then executes, logging each item.
- Flexibility: This method is useful for any operation that needs to be applied to each element of an array, such as transforming data, filtering, or aggregating information.
Practical Use and Efficiency
Using a FOR EACH loop is especially advantageous when you need to ensure that every element of a list or array is accessed and processed, as it automatically handles the traversal of the collection. This eliminates potential errors from manual index handling and makes the code cleaner and easier to read.
FOR EACH loops are particularly well-suited for collections where the operation does not need to modify the list's structure (i.e., not adding or removing elements during iteration), as it purely focuses on accessing each element.
Loop 4: Looping Through a List with a Counter-Controlled Loop
In this version of looping through a list, you use a counter to control the number of iterations based on the length of the list. This approach is a traditional method used in many programming languages, especially when specific indexing is necessary or when manipulating the index directly is part of the logic.
Explanation of the Given Code
The provided pseudo code demonstrates how to calculate the sum of all numbers in a list by iterating through each element using a counter-controlled loop:
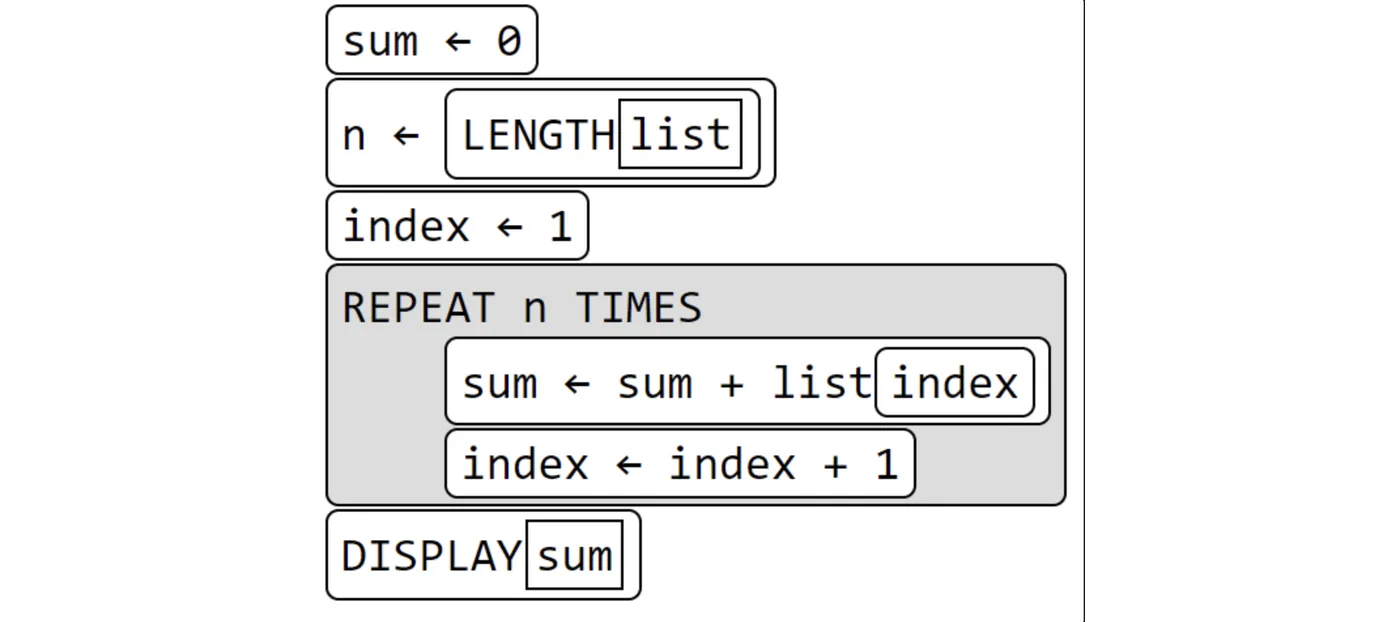
Step-by-Step Breakdown:
- Initialization:
- sum is initialized to 0. This variable will accumulate the total of all numbers in the list.
- n is set to the length of the list, determining how many times the loop will execute.
- index starts at 1, assuming list indexing begins at 1 (as per AP Computer Science Principles guidelines).
- Loop Execution:
- The loop is set to REPEAT n TIMES, equal to the number of elements in the list.
- Inside the loop:
- The current item in the list list[index] is added to sum.
- index is then incremented by 1 to move to the next item in the list on the subsequent iteration.
- Display the Result:
- After the loop completes (having iterated through each element of the list), the total sum is displayed using DISPLAY(sum).
Explanation of What’s Happening:
This loop methodically adds each number in the list to sum. By incrementing index each time, every element from the first to the last is accessed and added together. The final value of sum after the loop concludes is the total of all elements in the list.
Complete vs. Partial Traversals
- Complete Traversal: Every element in the list is accessed, like in the sum loop above or a FOR EACH loop that runs to the end.
- Partial Traversal: Only some of the elements are accessed. The loop below only displays the first 3 scores. A loop that stops as soon as it finds what it's looking for (like the findWord procedure later on this page) is also a partial traversal.
scores ← [90, 85, 72, 64, 98]
index ← 1
REPEAT 3 TIMES
{
   DISPLAY(scores[index])
   index ← index + 1
}
Output: 90 85 72
Tips for Managing Complexity in Loops:
- Use Pencil and Paper: Using pencil and paper to track the values through each iteration can be incredibly helpful. Write down the current value of sum and index at each step to visualize the process and ensure accuracy.
What is a Procedure?
A procedure, also known as a method or subroutine in some programming languages, is a named block of code that performs a specific task. It can be called multiple times throughout a program by invoking its name, which makes the code cleaner, more modular, and easier to manage.
Writing a Procedure on the AP Exam
PROCEDURE procName(parameter1, parameter2, ...)
{
   <block of statements>
}

PROCEDURE procName(parameter1, parameter2, ...)
{
   <block of statements>
   RETURN(expression)
}
Both forms take zero or more parameters. The first just runs its statements. The second also sends a value back with RETURN.
Why Use Procedures?
Procedures are used to avoid repetition of the same code lines across a program. By encapsulating a sequence of instructions into a single, reusable procedure, you can:
- Reduce Code Duplication: Streamline your codebase by writing the logic once and using it throughout the program wherever needed.
- Simplify Maintenance: Changes to a procedure affect all parts of a program that use it, making updates easier and less error-prone.
- Enhance Readability: Clear, well-named procedures make it easier for someone new to the code to understand what it does.
- Break a Big Problem into Smaller Ones: Procedures let you base the solution to a large problem on solutions to smaller subproblems, with a procedure for each one. A game might have separate procedures for moving the player, checking for collisions, and updating the score. Splitting a program into separate subprograms like this is called modularity.
- Generalize with Parameters: Instead of writing nearly the same code over and over, pull the shared part into one procedure and use parameters for the parts that change. Then the same procedure works for a whole range of inputs. This code reuse is a big part of how procedures manage complexity.
- Change the Inside Without Breaking the Outside: Because of procedural abstraction, a programmer can change how a procedure works inside (to make it faster, more efficient, or use less storage) without telling the people who use it, as long as it still does the same thing.
PROCEDURE showMultiple(num, times)
{
   DISPLAY(num * times)
}
showMultiple(4, 2)
showMultiple(4, 3)
One procedure with two parameters covers every case. These two calls display 8 12. Without parameters, you'd need a separate procedure for every combination.
Example of Procedure
Here's an example procedure that doubles each value in a list. (A procedure that adds all the numbers in a list, findTotal, is in the Common Algorithms section below.)
PROCEDURE doubling(list)
{
   count ← 1
   REPEAT LENGTH(list) TIMES
   {
      list[count] ← list[count] * 2
      count ← count + 1
   }
}
Explanation:
- Procedure Name: doubling
- Parameter: list (an array of numbers)
- Functionality: The procedure iterates over each element of the array, doubling its value.
- Return Value: None. There's no RETURN statement, so the procedure doesn't return a value. Its job is to change the values stored in list.
Calling a Procedure
- Parameters vs. Arguments: Parameters are the input variables listed in a procedure's definition. Arguments are the actual values passed in when the procedure is called. In the call doubling(myScores), the argument myScores is assigned to the parameter list.
- Calling Syntax: On the AP exam, you call a procedure with procName(arg1, arg2, ...). arg1 is assigned to the first parameter, arg2 to the second, and so on.
- Flow of Control: A procedure call interrupts the normal top-to-bottom order. The program jumps into the procedure and runs its statements. Once the last statement (or a RETURN) runs, it goes back to the spot right after the call and keeps going.
- Other Names: Depending on the language, procedures are also called methods or functions.
PROCEDURE greet(name)
{
   DISPLAY("Hi")
   DISPLAY(name)
}
DISPLAY("Start")
greet("Ana")
DISPLAY("End")
Output: Start Hi Ana End. The call greet("Ana") pauses the main program, runs both DISPLAY statements inside greet, and then the program picks up at DISPLAY("End").
Returning a Value
- RETURN: RETURN(expression) sends the value of expression back to where the procedure was called and ends the procedure right away. Any statements after it inside the procedure are skipped. A RETURN can appear anywhere in a procedure.
- Storing the Result: result ← procName(arg1, arg2) calls the procedure and assigns the value it returns to result.
PROCEDURE larger(x, y)
{
   IF(x > y)
   {
      RETURN(x)
   }
   RETURN(y)
}
result ← larger(4, 9)
DISPLAY(result)
Explanation: The argument 4 goes into x and 9 goes into y. Since 4 > 9 is false, the first RETURN is skipped, and RETURN(y) sends back 9. The program stores 9 in result and displays 9. With larger(12, 5), RETURN(x) would run, end the procedure right there, and return 12.
Built-In Procedures on the Reference Sheet
- DISPLAY(expression): Displays the value of expression, followed by a space. DISPLAY(1) followed by DISPLAY(2) shows 1 2 on the same line.
- INPUT(): Accepts a value from the user and returns it. name ← INPUT() waits for the user to type something and stores it in name.
Common Algorithms on AP Exam
Algorithms can be created from an idea, by combining existing algorithms, or by modifying existing ones. Knowing the common algorithms below (sum, average, maximum, minimum, searching, and checking divisibility) helps you build new ones. Using existing correct algorithms as building blocks cuts development time, means less testing, and makes errors easier to find, since you already know those parts work.
Algorithm Description: Find Total Sum of a List
The purpose of this algorithm is to compute the total sum of all elements in a list. This operation is frequently used in data analysis, financial calculations, and anywhere you need to aggregate numerical data.
PROCEDURE findTotal(scores)
{
   sum ← 0
   FOR EACH item IN scores
   {
      sum ← sum + item
   }
   RETURN(sum)
}
Breakdown of the Algorithm
- Initialization:
- sum ← 0: We start by initializing sum to 0. This variable will hold the cumulative total of the numbers as we iterate through the list.
- Loop Through Each Element:
- FOR EACH item IN scores: This loop iterates over each element in the list scores. The variable item takes on the value of each element in the list one by one.
- Accumulate the Sum:
- sum ← sum + item: Inside the loop, we add the current element (item) to the running total (sum). Each iteration updates sum to include the value of the current item.
- Return the Total:
- RETURN(sum): After the loop has processed all elements in the list, the procedure returns the total sum accumulated.
Understanding What’s Happening
- Loop Mechanics: The FOR EACH loop is straightforward and efficient for accessing each element in the list without manually handling the index. It ensures that every item in the list is considered.
- Accumulation Process: Each step of the loop adds the current item’s value to sum, effectively accumulating the total of all items in the list.
- Final Output: The final value of sum after all iterations is the sum total of all the elements in the list scores.
Understanding the Algorithm: Finding the Average of a List
Calculating the average of a list of numbers is a fundamental task in programming, used in countless applications to summarize and analyze datasets. Let's break down two versions of this algorithm written in pseudocode.
Implementation 1: Using FOR EACH Loop
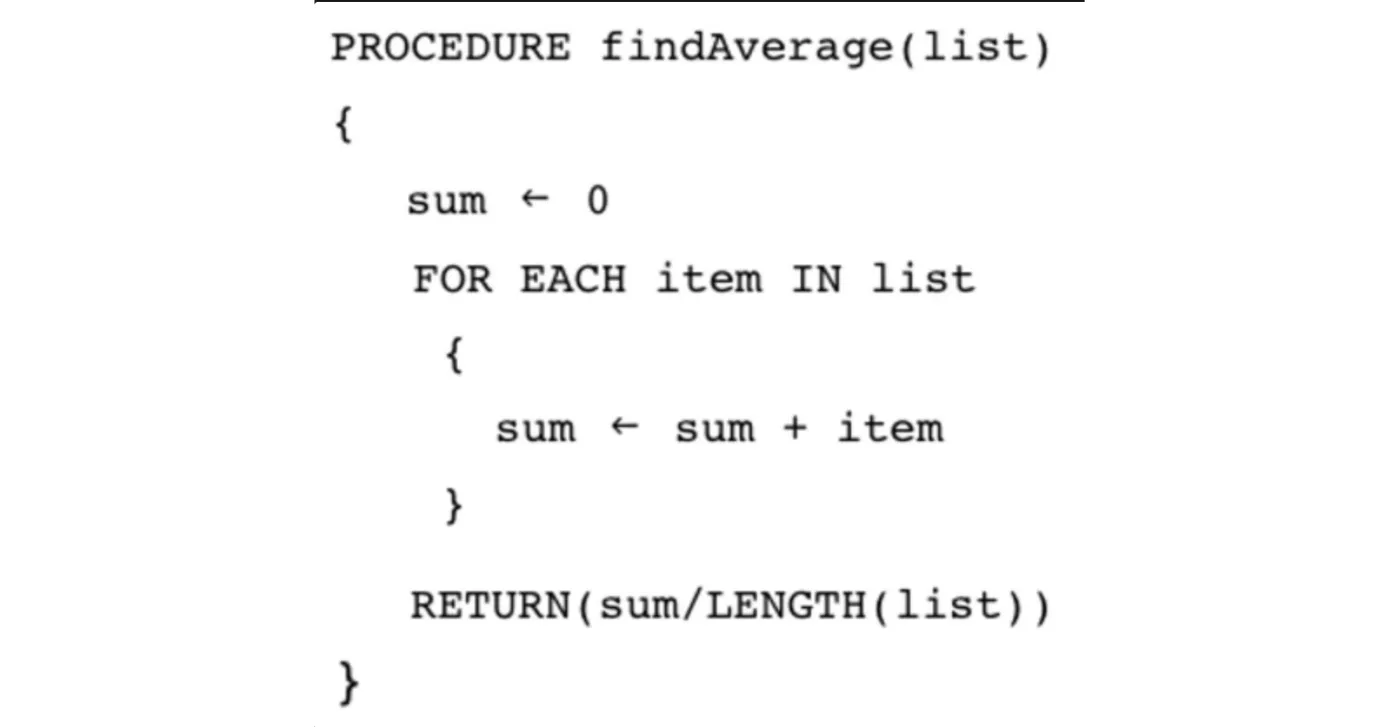
Step-by-Step Explanation:
- Initialization of sum:
- sum ← 0: Start with a sum of zero to which the values from the list will be added.
- Iterating Through the List:
- FOR EACH item IN list: This loop goes through each item in the list one by one.
- sum ← sum + item: In each iteration, the current item's value is added to sum.
- Calculating the Average:
- RETURN(sum / LENGTH(list)): After all items are added to sum, the average is calculated by dividing sum by the number of items in the list LENGTH(list). The RETURN statement outputs the result of this division, which is the average.
Implementation 2: Using REPEAT n TIMES Loop
PROCEDURE findAverage(list)
{
   sum ← 0
   n ← LENGTH(list)
   index ← 1
   REPEAT n TIMES
   {
      sum ← sum + list[index]
      index ← index + 1
   }
   RETURN(sum / n)
}
Step-by-Step Explanation:
- Initialization:
- sum ← 0: Initializes the sum to zero.
- n ← LENGTH(list): Stores the number of items in the list in n.
- index ← 1: Starts the index at 1, considering the AP exam's 1-based indexing.
- Looping Through the List:
- REPEAT n TIMES: The loop is set to iterate n times, which is the length of the list.
- Inside the loop:
- sum ← sum + list[index]: Adds the value at the current index of the list to sum.
- index ← index + 1: Increments the index to move to the next item in the list.
- Returning the Average:
- RETURN(sum / n): After all iterations, the loop has summed all elements in the list. Dividing this sum by n (the total number of items) gives the average. This value is then returned.
Understanding Both Implementations
- Key Difference: The first implementation uses a FOR EACH loop, which directly iterates over each element in the list, abstracting away the need for index management. The second implementation uses a REPEAT n TIMES loop, explicitly managing the index and ensuring it increments with each iteration.
- Conceptual Focus: Both methods aim to simplify calculating the average by first summing all elements and then dividing by the number of elements. However, the REPEAT n TIMES loop offers more control, particularly useful in scenarios where index-based operations are necessary beyond simple summation.
Same Task, Different Algorithms
The two findAverage procedures look different but always return the same answer. Algorithms can be written in different ways and still do the same task, and different algorithms can be developed to solve the same problem. The flip side matters just as much: algorithms that look almost the same can give different results. Compare these two:
// Algorithm A
count ← 0
REPEAT 3 TIMES
{
   count ← count + 1
   DISPLAY(count)
}

// Algorithm B
count ← 0
REPEAT 3 TIMES
{
   DISPLAY(count)
   count ← count + 1
}
Algorithm A displays 1 2 3, but Algorithm B displays 0 1 2. The only difference is the order of two lines. On the exam, trace both versions before deciding two algorithms do the same thing.
Conditionals and Boolean Expressions Can Be Equivalent
Some conditional statements can be written as a single Boolean expression, and some Boolean expressions can be written as conditional statements. These two code segments always give isEven the same value, because num MOD 2 = 0 is already true or false:
IF(num MOD 2 = 0)
{
   isEven ← true
}
ELSE
{
   isEven ← false
}

isEven ← (num MOD 2 = 0)
In the same way, a nested IF can often be written with AND. These two segments do the same thing:
IF(age ≥ 16)
{
   IF(hasLicense)
   {
      DISPLAY("Can drive")
   }
}

IF(age ≥ 16 AND hasLicense)
{
   DISPLAY("Can drive")
}
Understanding the Algorithm: Finding the Maximum of a List
Finding the maximum value in a list is a common task that involves comparing each element of the list to determine the largest one. Here, we'll break down two implementations of a procedure to find the maximum value in a list.
Finding the Maximum of a List (Implementation #1)
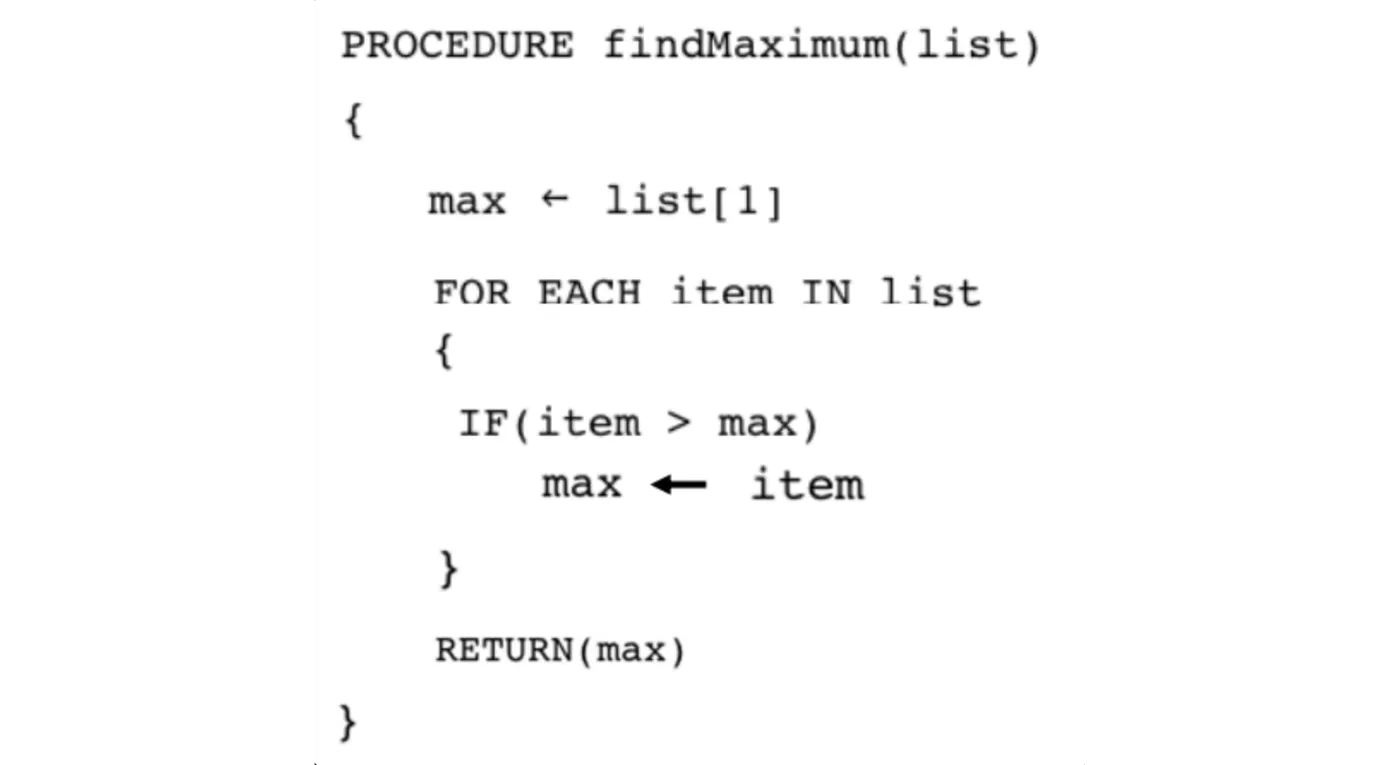
Step-by-Step Explanation:
- Initialize Maximum:
- max ← list[1]: Start by assuming that the first item in the list is the maximum. This sets a baseline for comparison.
- Iterate Through the List:
- FOR EACH item IN list: Loop through each element in the list.
- IF(item > max): Check if the current item is greater than the current maximum (max).
- max ← item: If the current item is greater, update max to this new value.
- Return the Maximum:
- RETURN(max): After finishing the loop, return the value of max, which now holds the maximum value found in the list.
Rationale Behind Implementation #1:
- The use of a FOR EACH loop simplifies the process of iterating over each element and focuses on the logic of comparing and updating the maximum value.
- This implementation is straightforward and very readable, making it easy to understand the logic of finding the maximum value.
Finding the Maximum of a List (Implementation #2)
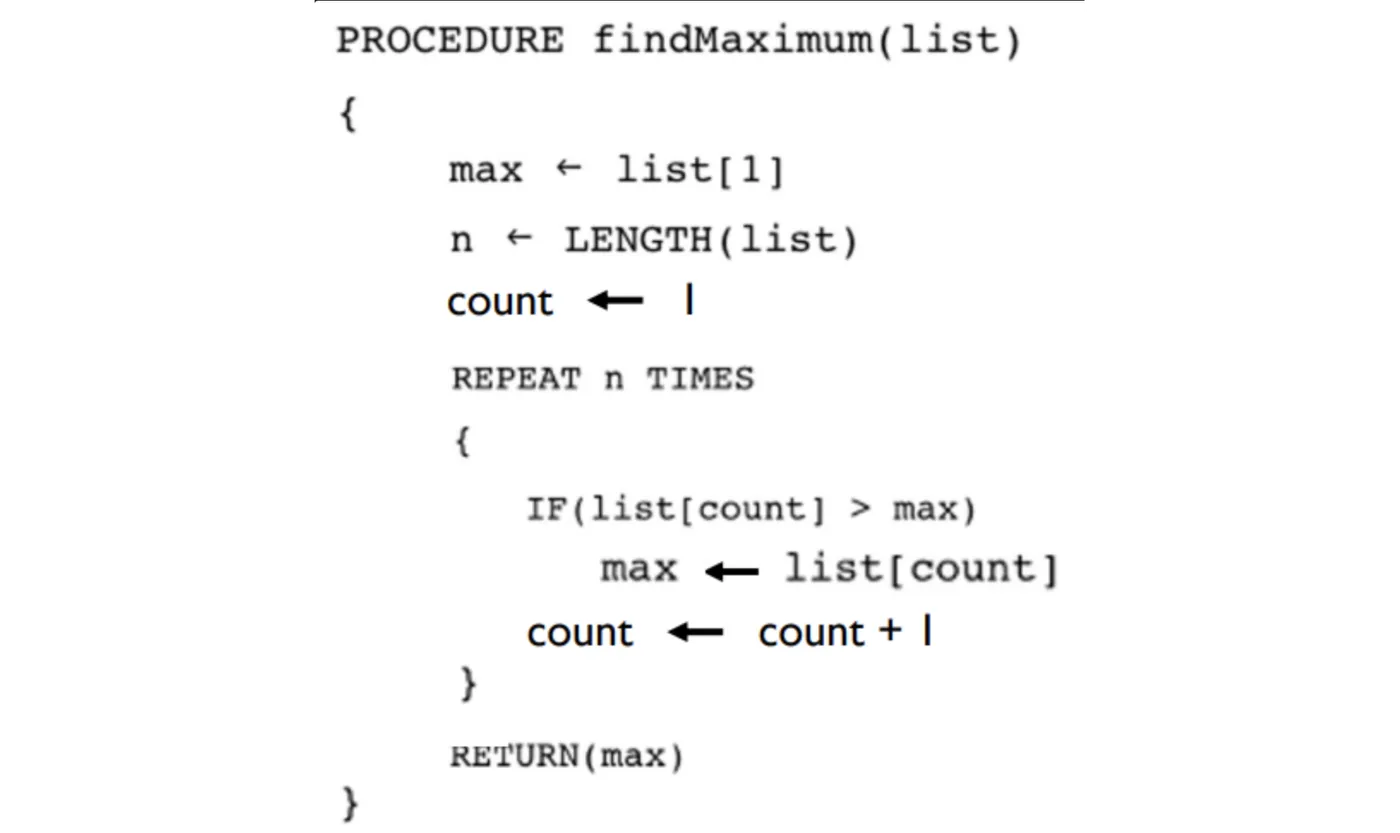
Step-by-Step Explanation:
- Initialize Variables:
- max ← list[1]: Initialize max as the first element in the list.
- n ← LENGTH(list): Determine the number of elements in the list and store it in n.
- count ← 1: Start a counter at 1 to use for indexing through the list.
- Loop Through the List Using a Counter:
- REPEAT n TIMES: Use a repeat loop to go through the list n times, once for each element.
- IF(list[count] > max): Inside the loop, check if the current element list[count] is greater than the current maximum.
- max ← list[count]: If true, update max to this new larger value.
- count ← count + 1: Increment count to move to the next element in the list.
- Return the Maximum Value:
- RETURN(max): After completing the loop, max will hold the highest value found, which is then returned.
Rationale Behind Implementation #2:
- This method explicitly manages the indexing of elements, making it clear how each element is accessed.
- The REPEAT n TIMES structure allows precise control over how many iterations occur, matching the exact length of the list.
- Manually handling the index with count gives flexibility if modifications to the looping mechanism are needed, such as skipping elements or other conditions based on the index.
Analysis of a Common Error in Finding the Maximum Value
The provided pseudo code contains a typical error that can easily lead to incorrect results, especially when working with specific types of data such as all-negative lists. Let's break down the error and understand why it happens.
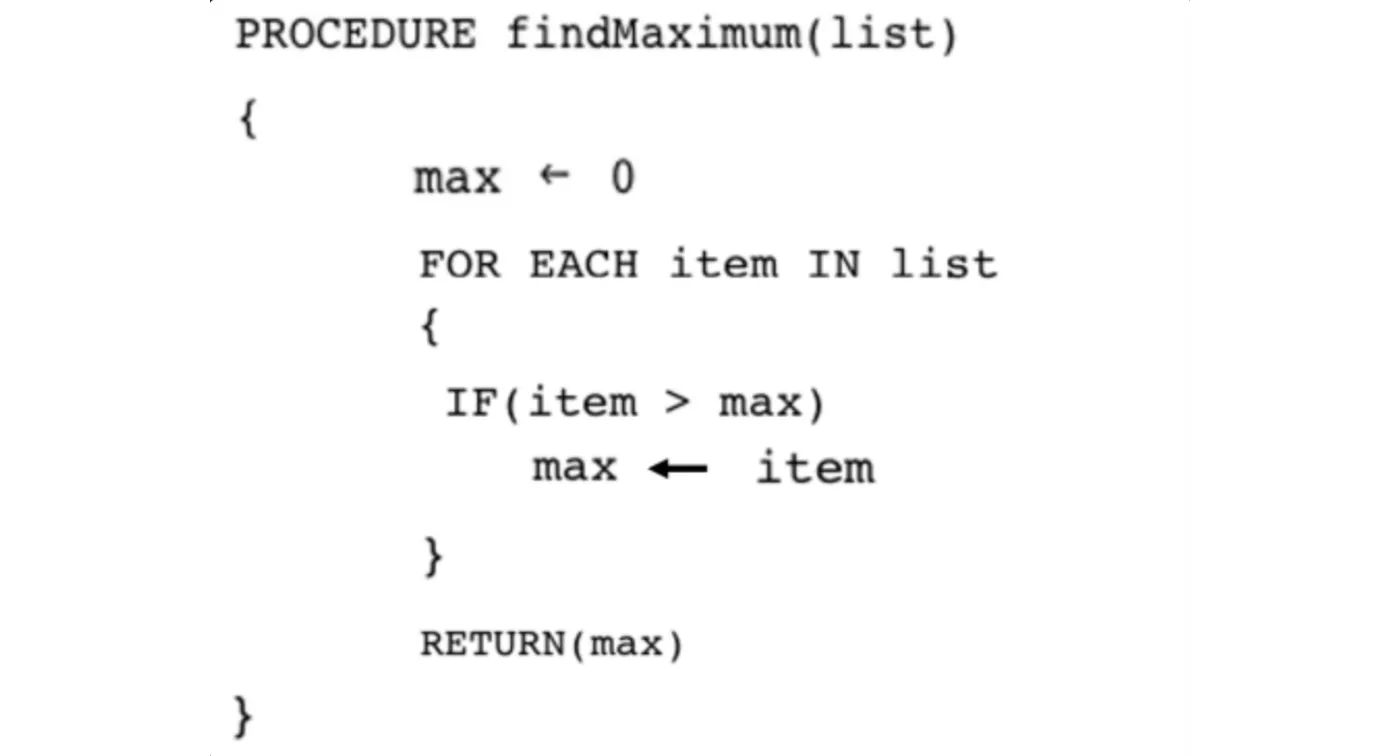
Issue with the Code:
The error in this code lies in the initialization of the max variable to 0. This approach assumes that the maximum value in any list will be at least 0, which is not always the case, particularly with lists containing all negative numbers.
Step-by-Step Breakdown with the Given List [-1, -1, -35, -6]:
- Initialization:
- max is initialized to 0. This is intended to provide a starting point for comparison.
- Loop Through Each Item in the List:
- The loop iterates over each element in the list: -1, -1, -35, -6.
- The conditional IF(item > max) checks if the current item is greater than max.
- Condition Evaluation:
- For each item in the list [-1, -1, -35, -6], the condition item > max is evaluated against max = 0.
- None of these items is greater than 0, so the condition never evaluates to true.
- Consequently, max remains unchanged at 0.
- Return Value:
- The function returns max, which remains 0, not reflecting any of the actual values in the list.
The Logical Error
The logical error is setting max to 0 at the start. For lists that contain only negative numbers, no element will ever be greater than 0, so max remains incorrectly set to 0. The algorithm fails to accurately assess the maximum in cases where all elements are below the initialized value of max.
Analyzing a Common Error in Finding the Minimum Value
The pseudocode provided for the procedure to find the minimum value in a list contains a significant logical error that results in an incorrect outcome. Let's dissect the error and explain why it occurs.
PROCEDURE findMinimum(list)
{
   min ← list[1]
   FOR EACH item IN list
   {
      IF(item < min)
      {
         min ← item
      }
      ELSE
      {
         min ← 0
      }
   }
   RETURN(min)
}
Issue with the Code:
The fundamental error in this code is in the ELSE branch of the conditional statement, which sets min to 0 whenever the current item is not less than the current minimum. Since min starts as list[1], the first item is never less than min, so min is reset to 0 on the very first pass, and after that the procedure loses track of the real minimum. It gives wrong answers even for lists of negative numbers: for [-5, -1], it returns -1 instead of -5.
Step-by-Step Breakdown with the List [1, 1, 35, 6]:
- Initialization:
- min is initialized to the first element of the list, which is 1. This is a good start as it represents a real value from the list.
- Loop Through Each Item:
- The loop iterates over each element in the list.
- Condition Evaluation and Update:
- First Iteration (item ← 1): Since 1 is not less than min (which is 1), the ELSE block executes, setting min to 0.
- Subsequent Iterations (items ← 1, 35, 6): For each of these items, since none of them are less than 0 (the newly set value of min), min remains 0.
- Return Value:
- The function returns min, which is now 0, clearly not the minimum value of the original list.
Explanation of What's Happening:
- The initialization and the loop's condition are correctly implemented; min is initially set to the first item, and the list is correctly iterated to find the minimum.
- The logical flaw is the reset of min to 0 in the ELSE clause. This reset is based on an incorrect assumption and should not be part of finding the minimum value.
Corrected Approach
The correct implementation should only update min when a smaller item is found and do nothing otherwise. The corrected pseudocode would look like this:
PROCEDURE findMinimum(list)
{
   min ← list[1]
   FOR EACH item IN list
   {
      IF(item < min)
      {
         min ← item
      }
   }

   RETURN(min)
}
Corrected Code Explanation:
- Eliminating the ELSE Clause: By removing the ELSE block, min only updates when a truly smaller value is found. If no smaller value is found, min remains correctly at the smallest value encountered.
Analyzing the Procedure to Find a Word in a List of Words
The provided pseudocode describes a procedure for finding the index of a specific word within a list. This is a fundamental search operation in computer science, often used to determine whether and where a particular element exists within a collection.
PROCEDURE findWord(list, word)
{
   index ← 1
   FOR EACH item IN list
   {
      IF(item = word)
      {
         RETURN(index)
      }
      ELSE
      {
         index ← index + 1
      }
   }

   RETURN("Word not in list")
}
Step-by-Step Breakdown:
- Initialization:
- index ← 1: Initializes the index to 1, assuming a list indexing starts at 1, which is typical for the AP exam format.
- Iterate Through the List:
- FOR EACH item IN list: Iterates through each item in the list sequentially.
- Check Each Item:
- IF(item = word): Checks if the current item matches the word we are searching for.
- IF true, RETURN(index): Immediately returns the current index, indicating where the word was found in the list.
- ELSE:
- index ← index + 1: Increments the index by one. This step is necessary to move to the next item's index in the list.
- Word Not Found:
- After the loop completes and if the word has not been found, RETURN("Word not in list"): This statement is executed if the word is not found in any iteration of the loop.
Algorithm: Checking if One Number Divides Evenly into Another
This uses MOD. If num MOD divisor is 0, there's no remainder, so num is evenly divisible by divisor.
PROCEDURE isDivisible(num, divisor)
{
   IF(num MOD divisor = 0)
   {
      RETURN(true)
   }
   RETURN(false)
}
isDivisible(12, 4) returns true because 12 MOD 4 is 0. isDivisible(10, 4) returns false because 10 MOD 4 is 2. Calling isDivisible(num, 2) checks whether num is even.
Understanding How to Swap Items in Arrays
Swapping items in an array is a common operation in programming that involves exchanging the positions of two elements. This process is crucial in various algorithms, especially in sorting and rearranging data.
Step-by-Step Explanation of Swapping
To simplify the concept of swapping items in an array, think of it like trading seats in a classroom:
- Create a Temporary Variable:
- Imagine you have a placeholder (a temporary seat or a placeholder card) where you can temporarily keep something. In the case of swapping, you use a temporary variable to safely store the value of one of the items you're going to swap.
- Replace the First Item with the Third Item:
- Say you initially sit in the first seat (position 1) and want to move to the third seat (position 3). Before moving, you take whatever is currently in the third seat and put it in the first seat.
- Replace the Third Item with the Item Stored in the Temporary Variable:
- Finally, move the item (or person) that was originally in the first seat (and now is in your temporary holding area) into the third seat.
Analogy:
Think of it as swapping lunch boxes between two friends. You don't want to mix up the contents, so you use an extra lunch box (the temporary variable) to hold the contents of one friend's lunch box while you swap them.
array ← ["apple", "banana", "orange"]

// Step 1: Store the first item in a temporary variable
temp ← array[1]
  // 'apple'

// Step 2: Replace the first item with the third item
array[1] ← array[3]
  // array now looks like ['orange', 'banana', 'orange']

// Step 3: Replace the third item with the item stored in the temporary variable
array[3] ← temp
DISPLAY(array)
Result: After step 3, array is ["orange", "banana", "apple"], so that's what DISPLAY(array) shows. The first and third items traded places, and "banana" never moved.
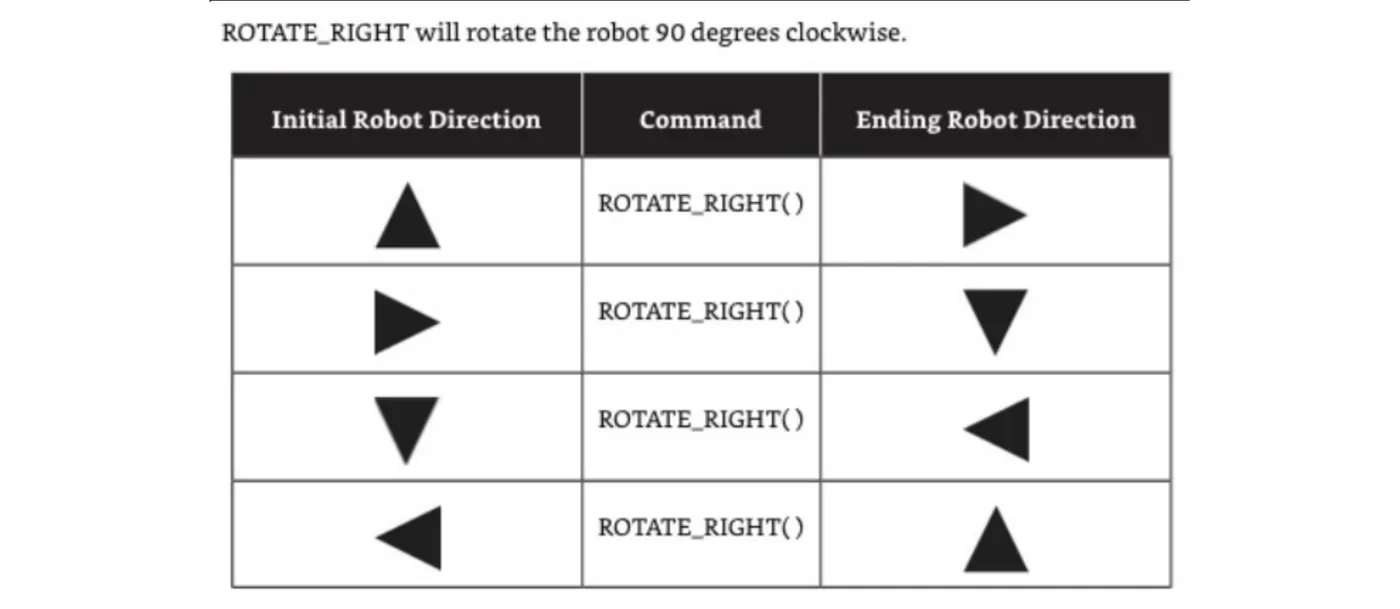
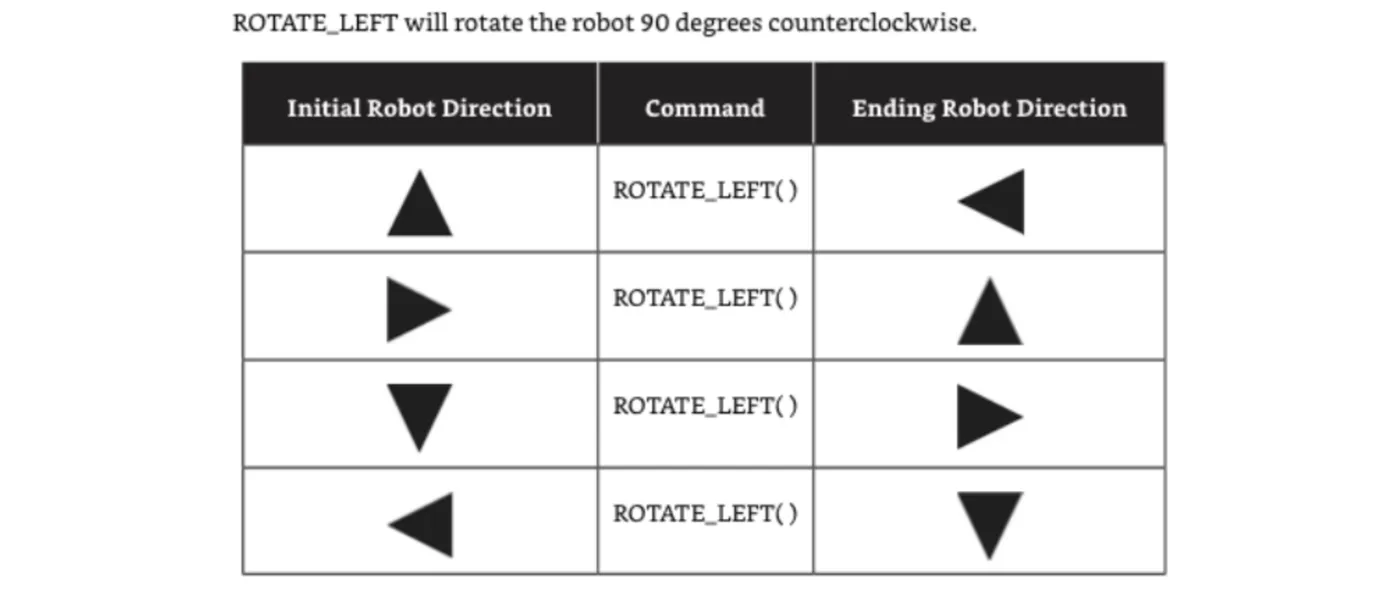
Understanding Robot Movement and Rotation Commands
To help students grasp the concept of robot movement and orientation, we can illustrate these actions using simple tables. These commands are commonly used in programming exercises, particularly in contexts like robotics and simulations, where directional control and movement are key aspects.
MOVE_FORWARD() Command and Conditional Movement
The MOVE_FORWARD() command moves the robot forward in the direction it is currently facing. To prevent the robot from moving into an obstacle or off the map, we use conditional checks.
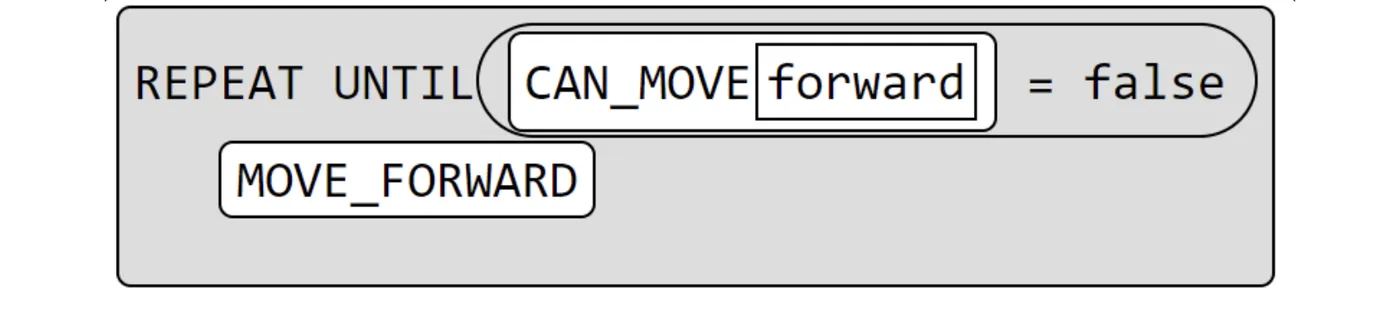
Explanation:
- REPEAT UNTIL Loop: This loop continues to execute the MOVE_FORWARD() command as long as the condition CAN_MOVE(forward) = true holds. Once CAN_MOVE(forward) returns false (indicating an obstacle or boundary ahead), the loop exits, and the robot stops moving.
Reaching a Goal
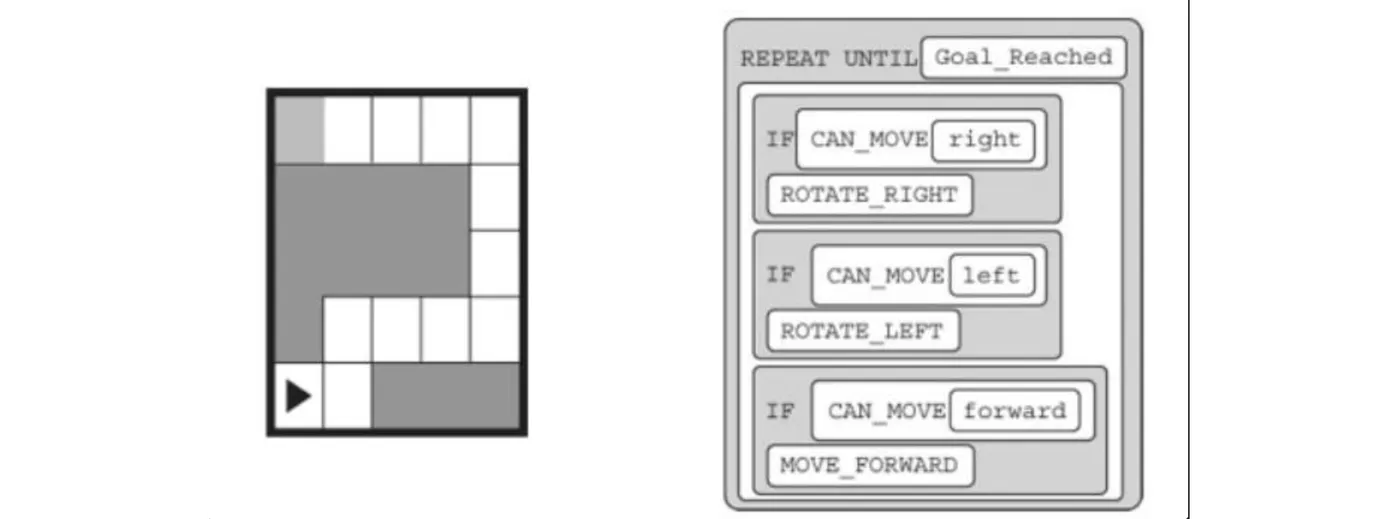
Explanation:
- Loop Execution: The loop executes repeatedly until the Goal_Reached condition becomes true. Inside the loop, you would include logic to move and rotate the robot as required to navigate towards the goal.
- Goal Condition: The Goal_Reached condition is checked continually. Once the robot arrives at the target location, the loop terminates, and the program can proceed to other tasks or end.
Understanding and Tracking Robot Movement on a Grid
When working with robot simulation tasks, such as on the AP Computer Science Principles exam, you might be required to predict possible landing spots after a series of movements and rotations. This can be tricky, but with a systematic approach and visualization tools like a pencil and paper, it becomes manageable. Let's explore how to tackle this using the provided pseudocode scenario.
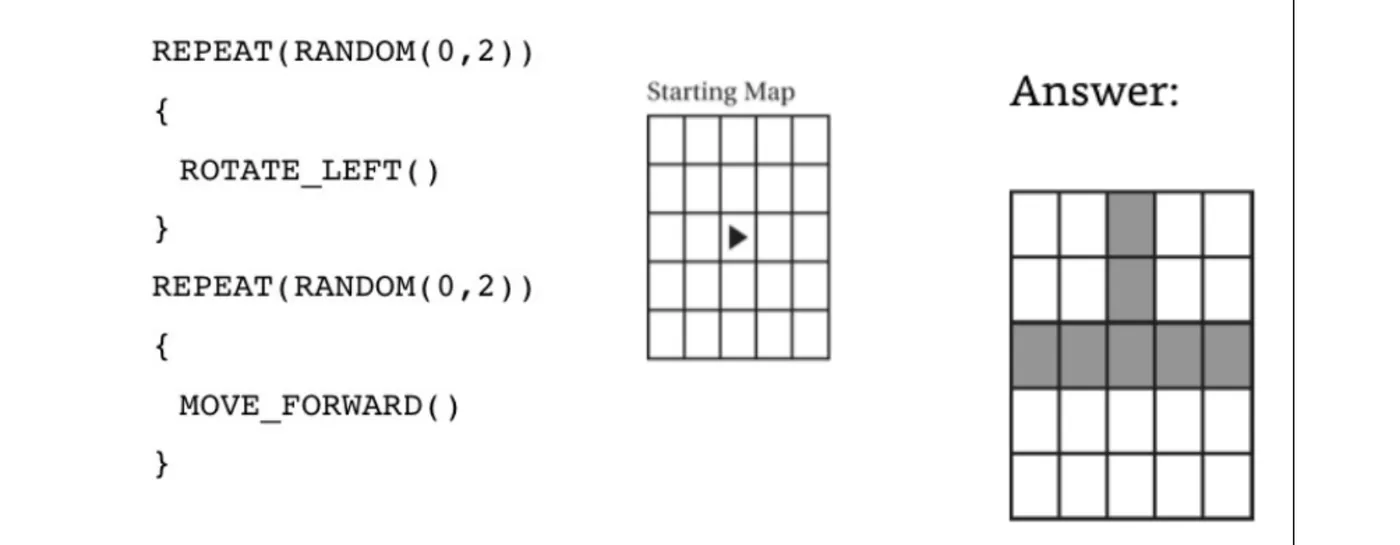
REPEAT RANDOM(0, 2) TIMES
{
   ROTATE_LEFT()
}
REPEAT RANDOM(0, 2) TIMES
{
   MOVE_FORWARD()
}
Breaking Down the Scenario
This scenario involves two separate randomized actions: rotating left a certain number of times and then moving forward a certain number of times. The randomness adds complexity because it introduces multiple possible outcomes for each action.
Step-by-Step Approach to Determine Possible Landing Spots
1. Understanding the Commands:
- ROTATE_LEFT(): Each call to this function rotates the robot 90 degrees counterclockwise.
- MOVE_FORWARD(): Moves the robot one tile forward in whatever direction it is currently facing.
2. Analyzing the Range of Actions:
- First REPEAT Loop: The robot could rotate 0, 1, or 2 times to the left. Each rotation changes the robot's facing direction:
- 0 times: Faces original direction.
- 1 time: Faces 90 degrees counterclockwise from the original.
- 2 times: Faces 180 degrees from the original.
- Second REPEAT Loop: The robot moves 0, 1, or 2 tiles forward in the direction it faces after the rotations.
3. Using a Pencil Method to Track Movement:
- Draw a Grid: Start with a 5x5 grid, and mark the robot's starting position at the center (column 3, row 3).
- Mark Rotations: For each possible rotation scenario (0, 1, 2 times), use an arrow to indicate the new facing direction from the center.
- Simulate Moves: For each facing direction, draw lines corresponding to moving forward 0, 1, or 2 tiles. Mark the end of each line. These are potential landing spots.
4. Testing Each Option:
- Eliminate Impossible Moves: If a move would take the robot off the grid, mark it as invalid.
- Count Valid Landing Spots: Note all the grid squares where the robot could potentially stop.
By physically drawing these paths on paper, you can visually track where the robot might end up based on different sequences of actions.
Answer: The robot starts in the center facing right. It can end on 7 squares: its starting square (if it moves 0 times), 1 or 2 squares to the right (0 turns), 1 or 2 squares up (1 turn), or 1 or 2 squares to the left (2 turns). It can never end below its start, since it turns left at most 2 times. These are the shaded squares in the answer.
Analyzing Robot Movement on a Grid with Random Actions
In this scenario, a robot on a 5x5 grid performs a series of random rotations and movements. The randomness in both rotations and movements introduces multiple possible outcomes, making it essential to systematically analyze the potential results. Here’s a step-by-step guide on how to figure out the robot's possible landing spots based on the given pseudocode.
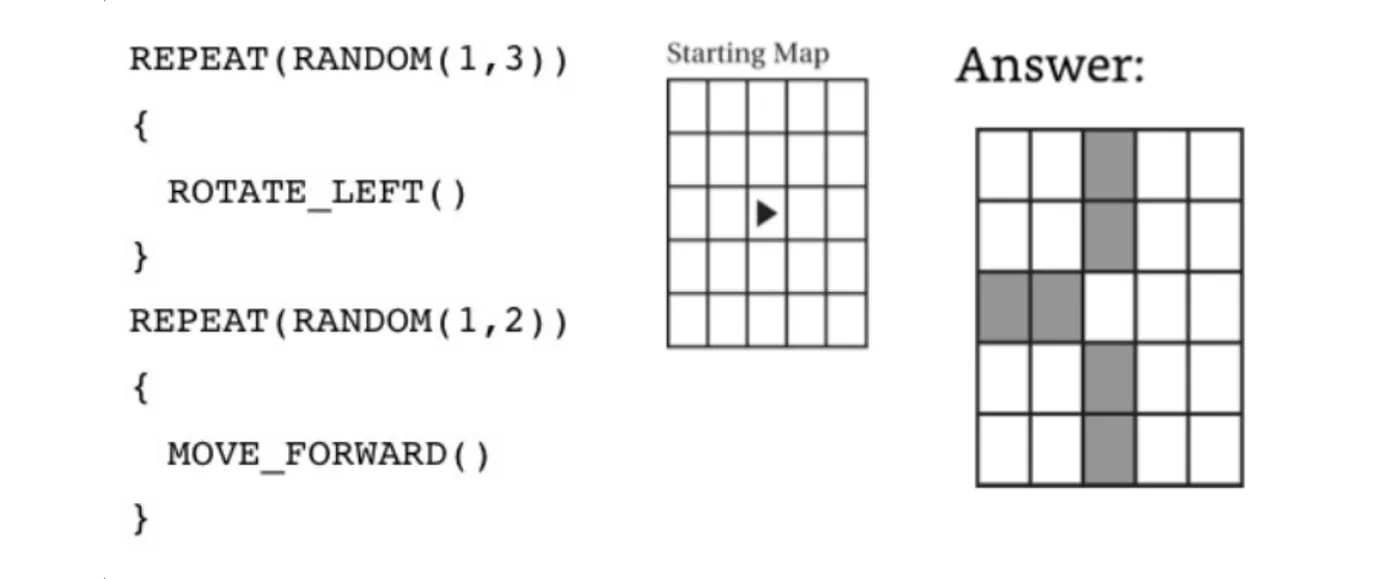
REPEAT RANDOM(1, 3) TIMES
{
   ROTATE_LEFT()
}
REPEAT RANDOM(1, 2) TIMES
{
   MOVE_FORWARD()
}
Step 1: Analyze the Rotation Command
- Command: ROTATE_LEFT()
- Randomness: The robot will rotate left between 1 and 3 times. Each ROTATE_LEFT() rotates the robot 90 degrees counterclockwise.
Possible Rotations:
- 1 rotation: The robot starts facing East (right, as in the starting map), so it ends up facing North.
- 2 rotations: The robot ends up facing West.
- 3 rotations: The robot ends up facing South.
Step 2: Analyze the Movement Command
- Command: MOVE_FORWARD()
- Randomness: The robot will move forward between 1 and 2 steps in whatever direction it is currently facing after the rotations.
Mapping Out the Movements on a 5x5 Grid:
- Draw the Grid: Sketch a 5x5 grid and mark the starting position in the middle (position C3, if using column-row notation).
- Mark Possible Rotations: From the center position, draw arrows in the directions the robot could potentially face after its rotations (North, West, South).
- Simulate the Movements:
- If facing West:
- Move 1 step west to B3.
- Move 2 steps west to A3 (if it doesn't exceed grid boundaries).
- If facing South:
- Move 1 step south to C2.
- Move 2 steps south to C1.
- If facing North:
- Move 1 step north to C4.
- Move 2 steps north to C5.
Step 3: Visualize and Mark Possible Endings
- For each direction the robot could face, use different colored pencils or markers to plot the 1-step and 2-step moves. This helps to visually differentiate the possible ending spots based on the number of steps taken.
Step 4: Evaluate and Consider Edge Cases
- Boundary Checks: Ensure that none of the movements take the robot off the grid. If a move would exceed the grid limit, it should not be considered a valid ending spot.
- Overlap Areas: There may be scenarios where different paths lead to the same grid cell. Mark these overlaps distinctly as they represent higher probability landing spots.
Answer: 6 possible landing spots: C4 and C5 (facing North), B3 and A3 (facing West), and C2 and C1 (facing South). The robot can't end on C3, since it always moves at least 1 step, and it can't end to the right of C3, since it turns left at least once and at most 3 times.
Understanding Linear Search
Linear search, also known as sequential search, is a fundamental search algorithm used in computing to find a specific element within a list. It works on both sorted and unsorted lists, making it one of the most straightforward searching techniques. Let's break down the process and how to calculate the number of comparisons needed to find an element.
How Linear Search Works
Linear search begins at the first element of the list and sequentially checks each subsequent element until the desired element is found or the list ends. This method is simple and does not require the list to be sorted, unlike more complex algorithms like binary search.
Key Points:
- Best Case Scenario: The best case occurs when the target element is the first item in the list. Here, only one comparison is needed.
- Worst Case Scenario: The worst case happens when the target is at the end of the list or not present at all. In such cases, the number of comparisons equals the number of elements in the list (n).
Examples of Linear Search
Example 1: Finding the Number '11' in a List
numList ← [“11”, “35”, “2”, “1”, “56”, “76”, “3”, “33”, “90”, “180”]
To find the number “11”:
- Start at the beginning of the list.
- Compare the first element with “11”'.
- Since the first element is “11”, the search is successful with just one comparison.
Example 2: Finding the Number ”180” in a List
To find the number “180”:
- Start at the beginning of the list.
- Sequentially compare each element with “180” until you reach the end of the list.
- ”180” is the last element in this list, so it would take 10 comparisons to find “180”
Calculating the Number of Comparisons Using Index
If you know the position (index) of an element in the list, you can directly determine the number of comparisons needed in a linear search:
numList ← [“11”, “35”, “2”, “1”, “56”, “76”, “3”, “33”, “90”, “180”]
- Index Method: The number of comparisons needed to find an element is equal to its index in the list
- Example Using Index:
- For “56” in numList, if we know “56” is at index 5:
- numList[5] = 56
- It takes 5 comparisons to find “56” using a linear search.
Understanding Binary Search
Binary search is an efficient algorithm for finding an element in a sorted list by repeatedly dividing the search interval in half. It is often much faster than linear search, especially for large lists, because each step cuts the remaining search space in half.
Why Binary Search Requires a Sorted List
Binary search operates under the assumption that the list is sorted in increasing order. This sorting allows the algorithm to decisively eliminate half of the search space after each comparison, based on whether the target value is greater or lesser than the middle element.
The Logic Behind Binary Search
Here’s the intuitive logic for why binary search works effectively:
- Initial Middle Comparison: Start by comparing the target value with the middle element of the list.
- Decision Process:
- If the target value is equal to the middle element, the search is successful.
- If the target value is less than the middle element, then it must be in the left half of the list (because the list is sorted in increasing order).
- If the target value is greater than the middle element, then it must be in the right half.
- Repeat Process: This process of halving the list is repeated on the new half (either left or right), continually narrowing down the possible locations of the target until it is found or the search space is exhausted.
Example of a Binary Search in Steps
Let's go through a step-by-step example of binary search on a sorted array:
sortedarray ← [2, 5, 8, 12, 16, 23, 38, 56, 72, 91]
Target to Find: 23
- Initial Middle: The middle element of [2, 5, 8, 12, 16, 23, 38, 56, 72, 91] is 16 (at index 5). With 10 elements there are two middle positions (5 and 6), and this example uses the lower one.
- Comparison: 23 is greater than 16, so we eliminate the left half of the array including 16.
- New Search Space: [23, 38, 56, 72, 91]
- New Middle: The middle of [23, 38, 56, 72, 91] is 56 (the 3rd element of the new search space, which is index 8 of the original list).
- Comparison: 23 is less than 56, so we eliminate the right half of the array including 56.
- New Search Space: [23, 38]
- New Middle: The middle of [23, 38] is 23.
- Comparison: 23 equals 23, so the search is successful.
Counting Iterations
That search took 3 iterations (3 comparisons with a middle element: 16, then 56, then 23). A linear search would have needed 6 comparisons, since 23 is at index 6.
To find the most iterations a binary search could need, find the smallest power of 2 that is greater than the number of elements. The exponent is the answer.
- 8 elements: at most 4 iterations, since is the first power of 2 greater than 8.
- 10 elements (like the list above): at most 4 iterations.
- 1,000 elements: at most 10 iterations, since . A linear search could need all 1,000.
- 1,000,000 elements: at most 20 iterations, since .
Doubling the size of a list adds only one more iteration to a binary search, but it doubles the worst case for a linear search. That's why binary search is often much more efficient on sorted data. The catch is that the data must be sorted first. For a small list, or one that isn't sorted, a linear search can be the better choice.
Comparison with an Unsorted Array
unsortedarray ← [5, 12, 2, 16, 23, 8, 56, 38, 72, 91]
If you attempted binary search on this unsorted array, the logic of halving based on greater or lesser comparisons breaks down. For example, finding 23 in this unsorted array via binary search would lead to incorrect eliminations and potentially not finding the target at all.
Understanding Flowcharts in Program Design
Flowcharts are essential tools in programming for visualizing the flow of logic in algorithms and processes. They use various standardized symbols to represent different types of actions or steps in a program. Let’s define these symbols and how they're used in a flowchart, and then look at an example flowchart with its corresponding trace.
Flowchart Symbols and Their Meanings
Here's a chart explaining the common symbols used in flowcharts:
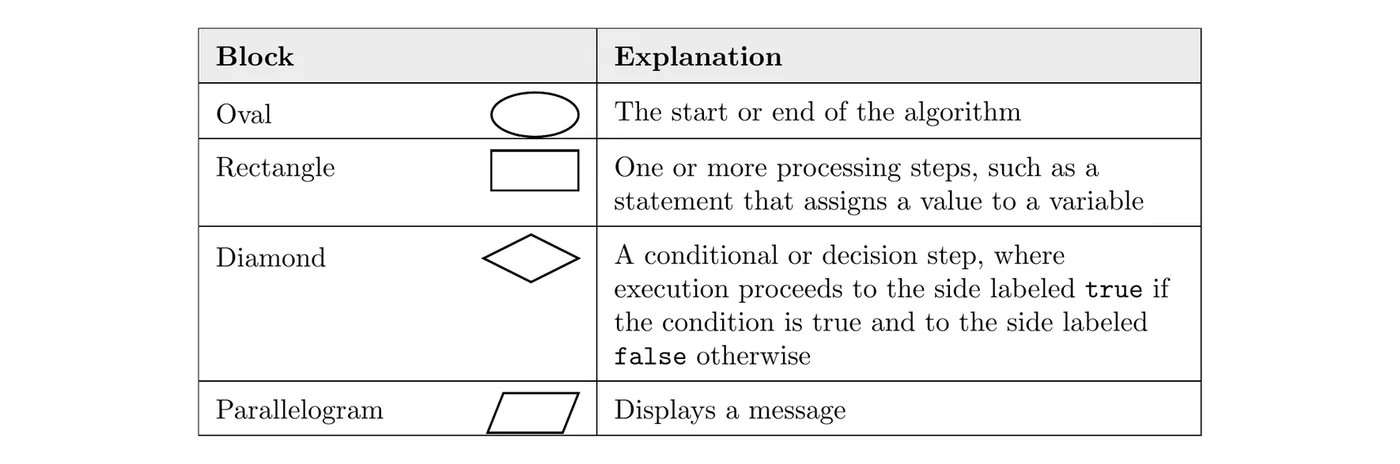
Tips for Tracing Flowcharts to Determine Outputs:
- Follow the Path: Start at the 'Start' symbol and follow the paths according to the input and decisions made at each diamond shape.
- Understand Decisions: Pay close attention to the decision symbols (diamonds). Ensure you understand the condition being tested.
- Look for Loops: If the flowchart contains loops, make sure to understand how many times the loop runs and under what conditions it stops.
- Check for Multiple Endpoints: Some flowcharts may have multiple end points depending on decisions made; ensure to trace each possibility based on different inputs.
- Use Scratch Paper: Write down or sketch the path you're following along with any variables' values to keep track of the process and outcomes.
Trace the code and determine the output of the following program.
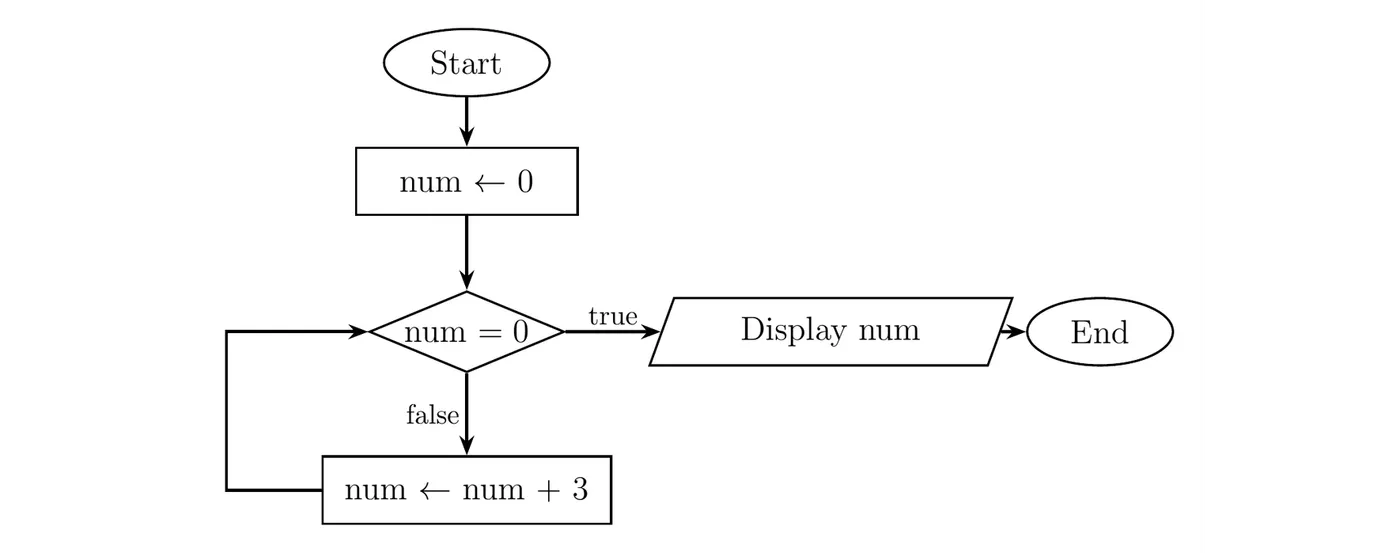
Answer:
Step 1: Start the program.
Step 2: Set num = 0.
Step 3: num equals 0, so the condition evaluates to true.
Step 4: Display 0.
Step 5: End the program.
Trace the code and determine the output of the following program.
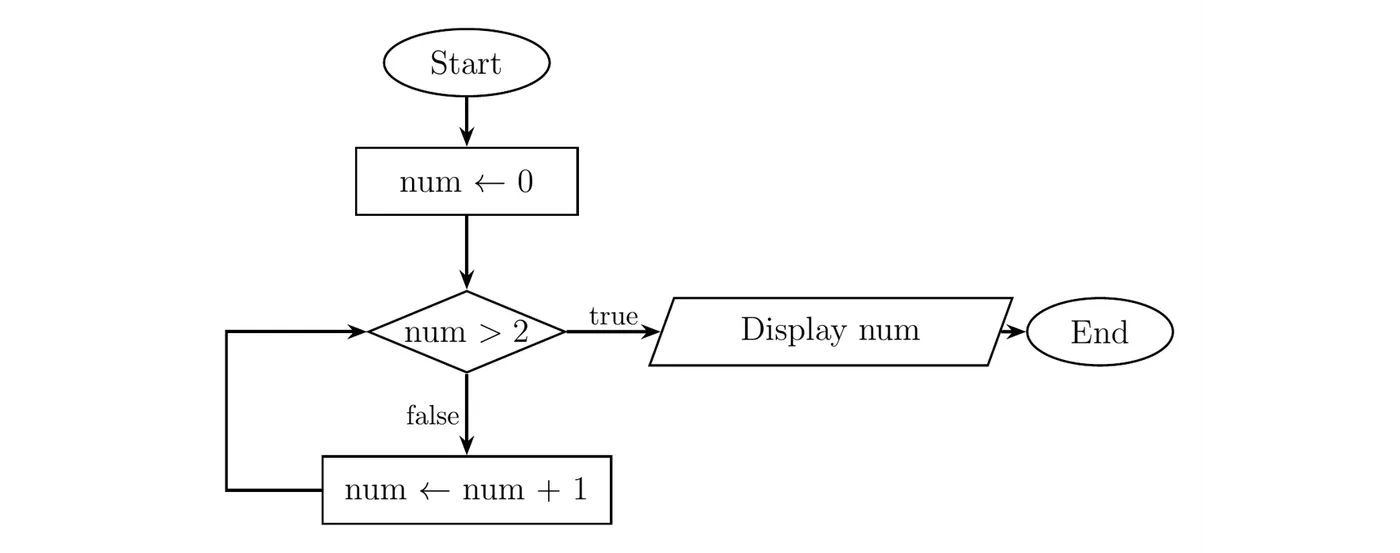
Answer: Display 3.
Algorithmic Efficiency
Some problems do not have efficient algorithms capable of solving them within a reasonable timeframe. Algorithms with polynomial efficiency (constant, linear, square, cube, etc.) are said to run in a reasonable amount of time, since they can be executed quickly on modern processors. However, many important and practical problems lack known polynomial-time algorithms and are tackled using algorithms with exponential or factorial efficiencies, which are generally too slow to be practical for large datasets.
Problems and Instances
- Problem: A general description of a task that can (or can't) be solved with an algorithm. Sorting is a problem.
- Instance: A problem with a specific input. Sorting the list (2, 3, 1, 7) is an instance of the sorting problem.
- Decision Problem: A problem with a yes or no answer, like "Is there a path from A to B?"
- Optimization Problem: A problem where the goal is to find the best solution out of many, like "What is the shortest path from A to B?"
Measuring Efficiency
Efficiency is an estimate of how much computing resources (like time and memory) an algorithm uses. It's usually described in terms of the size of the input: how much more work does the algorithm do as the input gets bigger? Efficiency is determined through formal or mathematical reasoning, but you can measure it informally by counting how many times a statement or group of statements runs.
REPEAT n TIMES
{
   REPEAT n TIMES
   {
      DISPLAY("*")
   }
}
The DISPLAY statement runs n times for each of the n passes of the outer loop, so it runs n × n times. That's 100 times when n is 10 and 1,000,000 times when n is 1,000. A single loop would run only n times. Different correct algorithms for the same problem can have very different efficiencies, like linear search (up to 1,000 checks for 1,000 items) and binary search (at most 10).
Reasonable vs. Unreasonable Time
Steps for an input of size n | n = 10 | n = 20 | Reasonable time? |
n (linear) | 10 | 20 | Yes |
n² (square) | 100 | 400 | Yes |
n³ (cube) | 1,000 | 8,000 | Yes |
2ⁿ (exponential) | 1,024 | 1,048,576 | No |
n! (factorial) | 3,628,800 | about 2.4 quintillion | No |
Algorithms whose number of steps grows like a polynomial (constant, linear, square, cube, and so on) run in a reasonable amount of time. Algorithms that grow exponentially or factorially run in an unreasonable amount of time: adding just a few more inputs can make them take longer than a lifetime.
Example: Finding the shortest route that visits every city on a list and returns home (the traveling salesperson problem) has no known efficient algorithm. Checking every possible route is factorial: from a fixed starting city, 10 cities give 362,880 orders to check, and 20 cities give more than 100 quadrillion. For problems like this, programmers look for approximate solutions instead.
Heuristic Approaches
A heuristic is a practical approach to solving problems where an optimal solution is impractical. Heuristics provide solutions that are good enough under the given circumstances. For example, a file-organizing algorithm that categorizes files based on a limited number of initial bytes offers a faster, though less comprehensive, solution than one which examines every byte.
A heuristic's answer is not guaranteed to be the best (optimal) one. Heuristics are used when the methods that always find the best answer would take too long to be practical. For the traveling salesperson problem, a heuristic could be "always drive to the closest city you haven't visited yet." It's fast and usually gives a decent route, but not always the shortest one.
Undecidable Problems
A decidable problem is a decision problem (yes or no answer) for which an algorithm can be written that gives the correct answer for every possible input. "Is this number even?" is decidable: check whether num MOD 2 = 0, and it works for any integer.
An undecidable problem is one for which no algorithm can ever be written that always gives a correct yes or no answer. This isn't about computers being too slow. It's proven to be impossible, no matter how much time or computing power you have.
- Example (the Halting Problem): Given any program and its input, will the program eventually stop, or will it run forever? In 1936, Alan Turing proved that no algorithm can answer this correctly for every possible program and input.
- Some Instances Can Still Be Solved: An undecidable problem may have some instances that an algorithm can solve. It's easy to tell that a short program with no loops will stop, for example. What's impossible is one algorithm that solves every instance.
You won't be asked to prove that a problem is undecidable. Just know what the terms mean and that undecidable problems exist.
Decomposition and Abstraction in Programming
Programmers often break down complex problems into smaller, more manageable components. By creating reusable procedures and leveraging parameters, they can abstract away the complexities of specific tasks. This abstraction allows programmers to rely on previously tested code, thereby speeding up development and enhancing confidence in their solutions.
Leveraging Software Libraries
Software libraries contain pre-written procedures that can be utilized in new programs. Examples include Python’s 'random' and 'numpy' libraries. These libraries simplify the task of developing complex programs by providing robust, pre-tested modules that implement common tasks.
Existing code segments can come from internal sources (procedures you or your team wrote earlier) or external sources (libraries other people wrote). Either way, reusing tested code means you don't have to write and debug everything from scratch.
Application Programming Interfaces (APIs)
APIs specify how the components of a library can be used in programming. For instance, Twitter's API allows developers to access and manipulate tweet data. Proper documentation of these APIs is crucial as it guides programmers on how to effectively use the provided functionalities.
Practice exam
Test yourself on Unit 3: Programming and Algorithms
Three exams for this unit in the real AP format, timed, with your score and what to study next.