Big Idea 4: Computer Systems and Network
Understanding Computing Devices, Systems, and Networks
Computing Devices: A computing device is a physical artifact capable of running a program. Examples of these devices include computers, tablets, servers, routers, and smart sensors. These devices are designed to receive inputs, process these inputs, and produce outputs based on the processed data.
Computing Systems: A computing system refers to a collection of computing devices and programs that work collaboratively to achieve a specific objective. This collaboration enhances the capabilities beyond what a single device could achieve independently.
Computer Networks: A computer network is an ensemble of interconnected computing devices that can send and receive data. Networks allow multiple devices to communicate and share resources efficiently. The bandwidth of a network refers to the maximum rate at which data can be transferred across the network in a given period of time.
Networks Are Computing Systems: A computer network is a type of computing system. The devices on a network (laptops, phones, servers, routers) and the programs running on them work together for one common purpose: sending and receiving data.
Measuring Bandwidth: Bandwidth is usually measured in bits per second (bps). Faster networks are described in kilobits per second (kbps), megabits per second (Mbps), or gigabits per second (Gbps). Since bandwidth is the maximum rate, real transfers are often slower. Example: a 50 megabyte (MB) file is 50 × 8 = 400 megabits, because 1 byte = 8 bits. On a connection with a bandwidth of 100 Mbps, it takes at least 400 ÷ 100 = 4 seconds to send.
Networking Concepts
Path and Routing:
- Path: In networking, a path is defined as a sequence of directly connected devices that begins with a sender and ends with a receiver.
- Example: when your laptop loads a web page, one possible path is laptop → home Wi-Fi router → your internet provider's routers → more routers across the Internet → the website's server. Each device in the path is directly connected to the next one.
- Routing: This is the process of finding a viable path from a sender to a receiver within a network. If a disruption occurs along the path, routing algorithms find an alternative path, showcasing the fault-tolerant nature of internet connections.
- Dynamic Routing: Routing on the Internet is usually dynamic, meaning the path is not set in advance. Routers choose where to send data next based on current conditions, like which connections are working. So two pieces of data going from the same sender to the same receiver can take different paths.
Internet Infrastructure
Components and Connectivity:
- The internet is a vast physical network composed of fiber optic cables, radio transmitters, and various forms of cabling. This infrastructure supports the global connectivity of devices and networks.
- A Network of Networks: The Internet is a computer network made up of many smaller networks connected together, like home networks, school networks, business networks, and cell phone networks. These networks can all communicate because they use the same standardized, open (nonproprietary) protocols (see Protocols below).
- Getting Connected: To access the Internet, a device has to connect to another device that is already connected to the Internet. For example, your phone connects to a Wi-Fi router or a cell tower, and that device is connected to the rest of the Internet.
Protocols and Internet Functionality:
- Protocol: A set of agreed-upon rules that dictate how data is transmitted across a network. Protocols ensure reliable and standardized communication between devices.
- Open Protocols: The Internet's protocols are open, meaning they are published for anyone to use for free and are not owned or controlled by one company. Because anyone can build a device or program that follows them, it is easy to connect new devices to the Internet.
- Internet Protocol (IP): IP is crucial for addressing and routing. It assigns unique addresses (IP addresses) to each device on the internet, facilitating precise data routing.
Scalability and Evolution of Internet Protocols:
- Scalability: This refers to the ability of a network or system to expand and adapt to increased demands. The internet's design allows it to scale up efficiently, accommodating more devices and data traffic without losing performance.
- Evolution of Protocols: Internet protocols have evolved to support the growing scale and complexity of global networks. This evolution is necessary to handle the increasing number of devices and the vast amount of data transmitted over the internet.
Transition from IPv4 to IPv6 and Networking Protocols
As technology advances and the number of devices connected to the internet increases, the protocols and infrastructure that support network communication must evolve. Here's an overview of the transition from IPv4 to IPv6, the roles of TCP and UDP, and the concepts of fault tolerance and redundancy in network systems.
IPv4 vs. IPv6
IPv4 (Internet Protocol version 4):
- Address Length: Uses 32 bits for IP addresses, allowing for approximately 4.29 billion unique addresses (2^32).
- Limitation: The explosive growth of the internet and connected devices has nearly exhausted the address capacity of IPv4, leading to the need for a more robust system.
IPv6 (Internet Protocol version 6):
- Address Length: Utilizes 128 bits, which significantly increases the number of possible IP addresses to about 3.4 x 10^38 (2^128). This expansion addresses the limitations of IPv4 and supports an expansive future growth of internet-connected devices.
- Benefits: Besides providing a larger address space, IPv6 includes enhancements for security, routing efficiency, and auto-configuration.
Know for AP Exam: 2^96 times as many addresses can be represented with IPv6.
Packets and Data Streams
Data sent over the Internet (an email, a photo, a video call) does not travel as one big piece. It travels as a data stream: the data is broken into small chunks, and each chunk is wrapped inside a packet.
- Packet: A small unit of data sent over the Internet. Each packet contains a chunk of the data plus metadata (data about the data).
- What the Metadata Is For: The metadata includes information used to route the packet from the origin to the destination, such as the sender's and receiver's IP addresses, and information used to reassemble the data, such as where the chunk belongs in the original message.
- How Packets Arrive: Because routing is dynamic, packets from the same message can take different paths. They may arrive at the destination in order, out of order, or not at all (a packet can be lost if a connection fails or a router gets overloaded). The receiving device uses the metadata to put the chunks back in the right order.
- Analogy: It's like mailing a book one page at a time in numbered envelopes. The envelopes might ride on different trucks and arrive in any order, or one might get lost, but the numbers let the receiver rebuild the book and see which page is missing.
- Common Internet Protocols: IP, TCP, and UDP are common protocols used on the Internet. IP handles addressing and routing each packet, while TCP and UDP control how packets are sent (see below).
TCP and UDP Protocols
TCP (Transmission Control Protocol):
- Functionality: TCP is a connection-oriented protocol that ensures reliable data transmission between computers on a network. It breaks data into packets, manages the packet sequencing, and retransmits any packets that are lost during transmission.
- Use Cases: Ideal for applications where accuracy is more critical than speed, such as web browsing, email, and file transfers.
UDP (User Datagram Protocol):
- Functionality: Unlike TCP, UDP is connectionless and does not guarantee the delivery of packets, meaning it does not resend lost packets. This makes it faster but less reliable.
- Use Cases: Suitable for applications where speed is more critical than reliability, such as streaming audio/video or gaming, where missing a few packets might not disrupt the user experience.
Network Fault Tolerance and Redundancy
Fault Tolerance:
- The internet is designed to be fault tolerant, meaning it can sustain operations even if part of the system fails. For example, if a route between two points on the internet is disrupted, the data will automatically be rerouted through an alternative path.
- Why It Matters: Parts of complex systems fail at unexpected times, and often several fail at once (for example, a storm or power outage can knock out many devices in one area). Fault tolerance lets people keep using the network even when this happens.
- Built In by Design: The Internet was engineered to be fault tolerant, with abstractions for routing and transmitting data. Routers automatically find new paths when something breaks, and TCP resends lost packets, so the sender and receiver don't need to know which path the data took or that something failed along the way.
- Only If Another Route Exists: When a device or connection fails, later data is sent along a different route, if one is possible. If every path between two devices goes through the part that failed, they can't communicate until it is fixed.
Redundancy:
- Redundancy involves creating multiple pathways and duplicate systems to ensure reliability and availability. In networking, having multiple routes between sender and receiver ensures that the failure of a single path does not interrupt data transmission.
- The Cost: Redundancy usually requires additional resources (extra cables, routers, and servers, plus the money to build and maintain them), but it gives the benefit of fault tolerance.
- Reliability and Growth: Having many possible routes between two points makes the Internet more reliable. It also helps the Internet scale to more devices and more people, because traffic can spread out over many paths instead of depending on one.
Example: Identifying Vulnerabilities in a Network
In the network below, each circle is a computing device and each line is a direct connection between two devices.
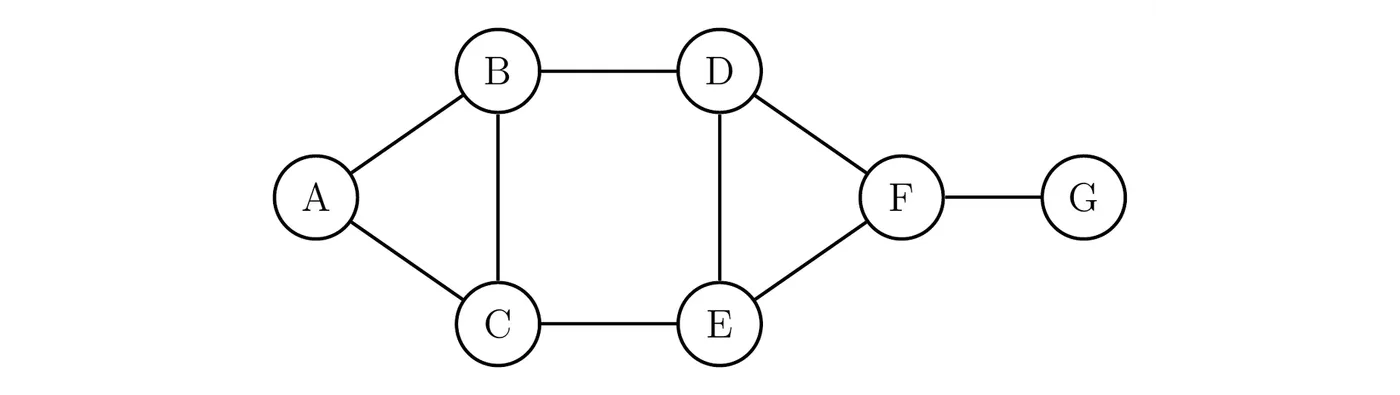
- Can A still send data to F if the connection between B and D fails? Yes. The data can take the path A → C → E → F instead.
- What is the fewest number of connections that would have to fail for A and F to be unable to communicate? 2. No single failed connection can do it, because there is always another route. But if both of A's connections (A to B and A to C) fail, A is cut off. Other pairs work too, like B to D and C to E, or D to F and E to F.
- Where is this network vulnerable? Device G has only one connection, to F. If the connection between F and G fails, or if device F itself fails, G can't communicate with any other device. Adding a second connection, like one between G and E, would fix this. It costs an extra connection, but it gives G a backup route (fault tolerance).
The Internet vs. The World Wide Web
- The Internet: A computer network made up of many interconnected networks that use standardized, open communication protocols. It includes the physical hardware (computers, routers, fiber optic cables, and radio transmitters) that lets billions of devices connect and communicate.
- The World Wide Web: Is a service built on top of the internet. It uses the HTTP protocol to transmit data and is made up of interconnected web pages and web applications.
- How They Relate: The World Wide Web uses the Internet. The Web is a system of linked pages, programs, and files, and HTTP is the protocol it uses to request and send them. When you open a website, your browser sends an HTTP request to a web server, and the request and the page travel across the Internet in packets. Other services, like email and most online games, also use the Internet without being part of the Web. So the Web is one of many things that run on the Internet, not the Internet itself.
Understanding Sequential vs. Parallel Computing
When examining computational models, it's crucial to distinguish between sequential and parallel computing, as each has different implications for processing speed and efficiency. Here's a breakdown of these concepts along with a method to calculate the "speedup" achieved through parallel processing.
Comparing Efficiency: One way to compare the efficiency of two solutions is to compare how long each one takes to do the same task. The solution that finishes in less time is more efficient.
Sequential Computing
Definition:
- Sequential computing is a process where operations are performed one after another. Each step must be completed before the next begins, resulting in the total processing time being the sum of all individual steps.
Example Calculation:
- Suppose a task involves the following sequential steps with their respective times (in seconds): 4, 1, 6, 2, 3, 1, 5, 1.
- Total processing time = 4 + 1 + 6 + 2 + 3 + 1 + 5 + 1 = 23 seconds.
Parallel Computing
Definition:
- Parallel computing breaks a program into multiple smaller sequential operations, some of which are done at the same time (simultaneously) on different processors or across a network of computers. A parallel solution has a sequential portion (steps that still have to run one after another) and a parallel portion (steps that run at the same time). The total time is the time of the sequential steps plus the time of the longest parallel task. If none of the steps have to wait on each other, there is no sequential portion, so the total time is just the longest parallel task.
Example Calculation of Parallel Processing Time:
- If the same task is split where the longest sub-task takes 9 seconds, then the parallel processing time is 9 seconds.
- For example, if all 8 steps are independent and are split across 3 processors: Processor 1 runs 4 + 5 = 9 seconds, Processor 2 runs 6 + 2 = 8 seconds, and Processor 3 runs 3 + 1 + 1 + 1 = 6 seconds. The processors work at the same time, so the task is done when the slowest one finishes: 9 seconds.
- That's one possible split, not the fastest. Putting 6 + 2 on Processor 1, 5 + 3 on Processor 2, and 4 + 1 + 1 + 1 on Processor 3 finishes in 8 seconds, the minimum for 3 processors. When a question asks for the minimum time, balance the work so the processors finish at about the same time.
Mixed Model Calculation:
- If parallel computing involves some steps that must be executed sequentially alongside parallel tasks, the total time is the sum of all sequential tasks plus the time taken for the longest parallel task.
- Example:
- Sequential tasks: 2, 1
- Parallel tasks: 4, 3, 1
- Total parallel processing time = 2 + 1 + max(4, 3, 1) = 3 + 4 = 7 seconds.
Speedup Calculation
Speedup is a measure of how much faster a parallel system is compared to a sequential system for the same task.
Formula: Speedup = Sequential run time / Parallel run time
Example of Speedup Calculation:
- Sequential time: 23 seconds
- Parallel time: 9 seconds
- Speedup = 23/9 = 2.56
- This result means the parallel solution is approximately 2.56 times faster than the sequential solution.
Example: Splitting Work Between Two Processors
A computer has two processors that can run at the same time. It needs to run four independent processes (none depends on another): P1 takes 20 seconds, P2 takes 35 seconds, P3 takes 15 seconds, and P4 takes 30 seconds. What is the fastest way to run them?
- Sequential time: 20 + 35 + 15 + 30 = 100 seconds.
- Try different splits: Each processor runs its processes one after another, and the job is done when the slower processor finishes.
- P1 + P2 = 55 and P3 + P4 = 45, so it takes 55 seconds.
- P1 + P3 = 35 and P2 + P4 = 65, so it takes 65 seconds.
- P1 + P4 = 50 and P2 + P3 = 50, so it takes 50 seconds.
- Best split: P1 and P4 on one processor, P2 and P3 on the other, for a parallel time of 50 seconds. Giving one processor three or more of the processes is slower, since that processor would have at least 15 + 20 + 30 = 65 seconds of work.
- Speedup = 100 / 50 = 2. The best split balances the work so both processors finish at about the same time.
Limits of Parallel Computing
Adding more processors only speeds up the parallel portion. The sequential portion takes the same time no matter how many processors there are, so it limits how efficient the solution can get. At some point, adding more parallel processing no longer meaningfully increases efficiency.
Example: A program has 10 seconds of steps that must run in order (sequential portion) and 40 seconds of work that can be split evenly among any number of processors (parallel portion).
Processors | Time (seconds) | Speedup |
1 | 10 + 40 = 50 | 1 |
2 | 10 + 20 = 30 | 1.67 |
4 | 10 + 10 = 20 | 2.5 |
8 | 10 + 5 = 15 | 3.33 |
20 | 10 + 2 = 12 | 4.17 |
40 | 10 + 1 = 11 | 4.55 |
- Going from 1 to 2 processors saves 20 seconds, but going from 20 to 40 processors saves only 1 second.
- The time can never drop below the 10 second sequential portion, so the speedup can never reach 50 / 10 = 5, no matter how many processors are added.
Understanding Distributed Computing
Distributed computing is a powerful approach used to tackle large and complex problems that exceed the capabilities of a single computer, particularly in terms of processing power and memory capacity. Let’s explore how distributed computing compares to parallel computing and why it's essential for solving certain types of problems.
Distributed Computing Defined
Distributed Computing:
- Concept: In distributed computing, a problem is divided across multiple computing devices (nodes). These nodes can be located in the same physical location or spread across different geographical areas, interconnected via a network.
- Advantages:
- Scalability: By adding more nodes to the system, distributed computing environments can scale to handle tasks of almost any size and complexity.
- Flexibility: Systems can be expanded or upgraded incrementally, which is more cost-effective than scaling up a single supercomputer.
- Fault Tolerance: The failure of a single node does not necessarily prevent the entire system from continuing its operation. Redundant data storage and functional backups can keep the system running smoothly despite individual component failures.
- Problems Too Big for One Computer: Distributed computing allows problems to be solved that could not be solved on a single computer, because they would take too much processing time or need more storage than one computer has. It also lets very large problems be solved much faster than one computer could.
- Example: A search engine stores and searches copies of billions of web pages. No single computer could hold all that data or answer millions of searches quickly, so the work is spread across thousands of servers in data centers.
- Example: Folding@home splits huge science simulations (like how proteins fold) into small pieces and sends them to volunteers' computers around the world. Together, those computers finish work that would take a single computer far too long.
Parallel vs. Distributed Computing
While both distributed and parallel computing involve running processes concurrently, they differ mainly in their structure and use cases:
- Parallel Computing: Breaks a program into smaller operations and runs some of them at the same time, often on multiple processor cores within the same computer. This is effective for tasks that require significant processing power but are limited by the physical and memory constraints of a single machine.
- Distributed Computing: Spreads tasks across multiple, often heterogeneous, machines which may not share a physical connection but are linked through a network. This model is suitable for very large data sets and computationally intensive tasks that no single machine could handle efficiently.
Benefits and Challenges of Parallel and Distributed Computing
- Benefits:
- Faster: Doing many steps at the same time finishes a task faster than doing them one at a time.
- Scales Better: Solutions that use parallel computing scale more effectively than sequential ones. When a problem gets bigger, you can add processors to share the extra work, while a sequential solution just takes longer.
- Bigger Problems: Distributed computing can solve problems that need too much time or storage for one computer.
- Challenges:
- The Sequential Portion: Steps that must run in order can't be sped up by adding processors, so they limit the total speedup (see Limits of Parallel Computing above).
- Waiting and Coordination: Some steps need the results of other steps, so they can't start until those finish. Splitting up the work and combining the results also takes extra time.
- Communication: In distributed computing, devices send data to each other over a network. This adds delay, and a failed device or connection can hold up the work unless the system is fault tolerant.